

Introducing pipelines
About pipelines

Quantemplate pipelines take raw input data – either from a Feed, or uploaded directly – then cleanse, transform, validate and enrich it via user-defined operations.
Data table concepts
Quantemplate pipelines take datasets in unstructured/semi-structured
formats such as spreadsheets, transforming them into harmonised, structured data tables.
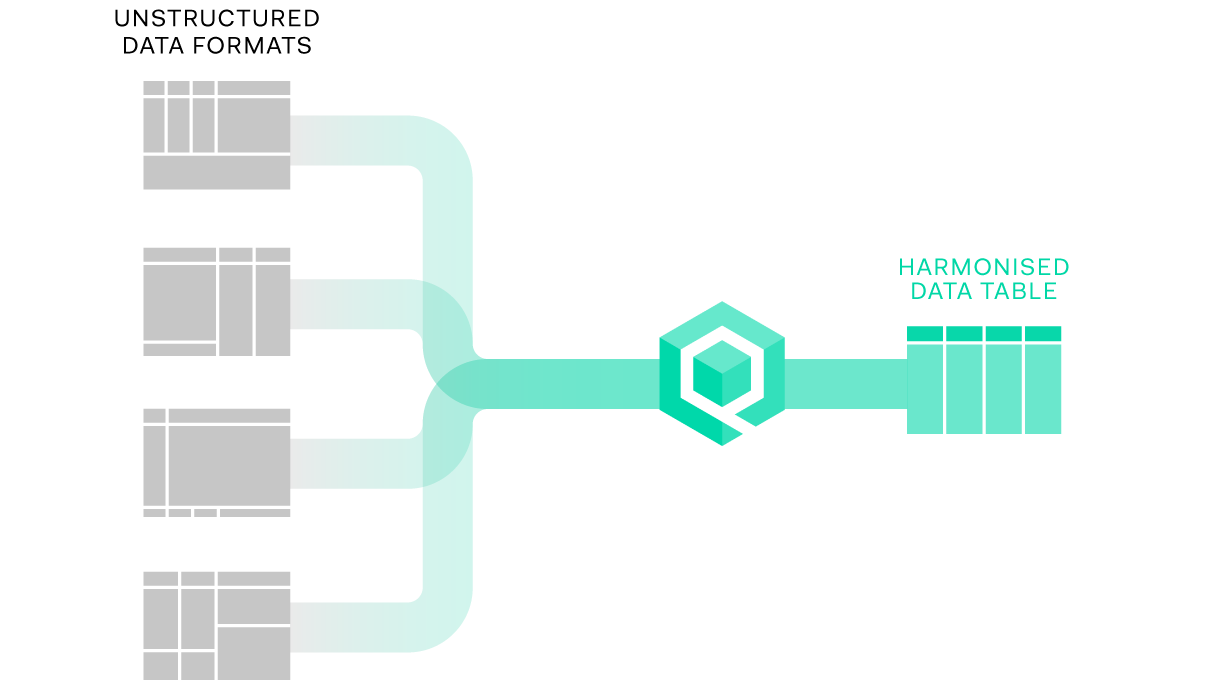

Data tables have a simple structure consisting of a set of columns and an unlimited number of rows.

Columns are the field names, represented as a set of headers at the top of a table.

Values are the individual data points. Quantemplate does not generally mandate a type of value (number, string, date) for a column, though certain functions require a certain value type:
- Arithmetic functions in Calculate need numbers.
- Date functions in Calculate and inputs to the Date Output operation need dates in Basic ISO format. Read more about working with dates.
- Values in the Aggregate operation need to be numbers.

Rows are collections of related data values, with one value for each column, usually represented as horizontal rows in Quantemplate.
How Quantemplate pipelines are different from Excel
Unlike spreadsheet tools such as Excel, Quantemplate pipelines apply a rules-based approach to configure batch processing actions across multiple datasets. This allows you to build repeatable processes to cleanse and harmonise data at scale.
Because it's built for defining data processing rules, Quantemplate pipelines do not allow:
- Cell-level alterations of individual values. To change a value, set up a transformation targeting the type of value you wish to change.
- Table presentation such as multiple layers of headers, headers along the side of the table, totals of rows or columns. Quantemplate Analyse provides tools to configure table presentation, add totals, apply filters, etc.
- Presentational number formatting such as millions, billions, %. Quantemplate Analyse provides tools to apply presentational formatting to numbers.
Components
Pipelines
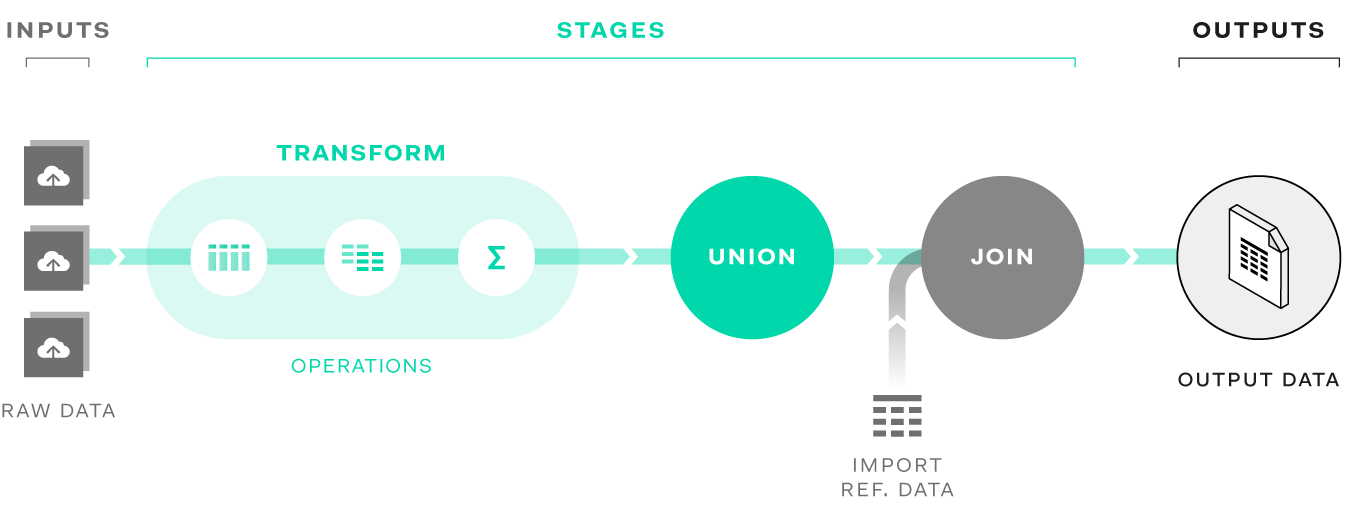
A pipeline is a data transformation process built for a set of input datasets, transforming them to a desired set of output datasets. A pipeline comprises:
- The uploaded input datasets.
- Stages and operations required to transform the data.
- Transformed output datasets.
- Validation report on the results of any validation operations in the pipeline.
- Run information including pipeline run events, metadata and the complete history of outputs for different runs.
- History of edits made to the pipeline
Input data
Raw data for cleansing is uploaded directly via the inputs interface. Quantemplate supports data in XLS, XLSX, CSV and GZipped CSV formats. Cleansed data such as other pipeline outputs or reference codes can be stored in the Data tab and connected to a pipeline.
Stages and operations
Data transformations are sequenced and configured via stages and operations. Stages are structural components with a defined number of input and output datasets, whilst operations are individual transformation processes, grouped together in a Transform stage. See Stages and operations for more details.
Output data
Each stage creates output datasets which are the result of the input data, modified by the operations within the stage. A stage’s output datasets can be connected to the inputs of a subsequent stage for further transformation, or can be exported to the Data tab, downloaded or shared with another organisation.
Pipeline runs
Pressing the Run button executes the pipeline transformations and creates the output datasets. The inputs and output datasets from each run of the pipeline are retained, and can be previewed, exported or downloaded.