

Regex
About the Regex operation
The Regex operation allows you to find data matching a certain pattern which can then be extracted or changed. For example:
- Extract the house number from a column of addresses
- Remove non-alphanumeric characters from a list of company names
Patterns are defined using a language known as 'Regular Expressions', commonly called Regexes.
Regex tutorial
- Substitute ‘Rd’ for ‘Road’
You can now use the Substitute function in Calculate - Change a four-digit zip code to a five-digit zip code
In Calculate, you can now use the expression:
RIGHT(CONCATENATE("00000", 'Column-name'), 5) - Change a date format
Use the Date Cleanse and Date Output operations
Workspace
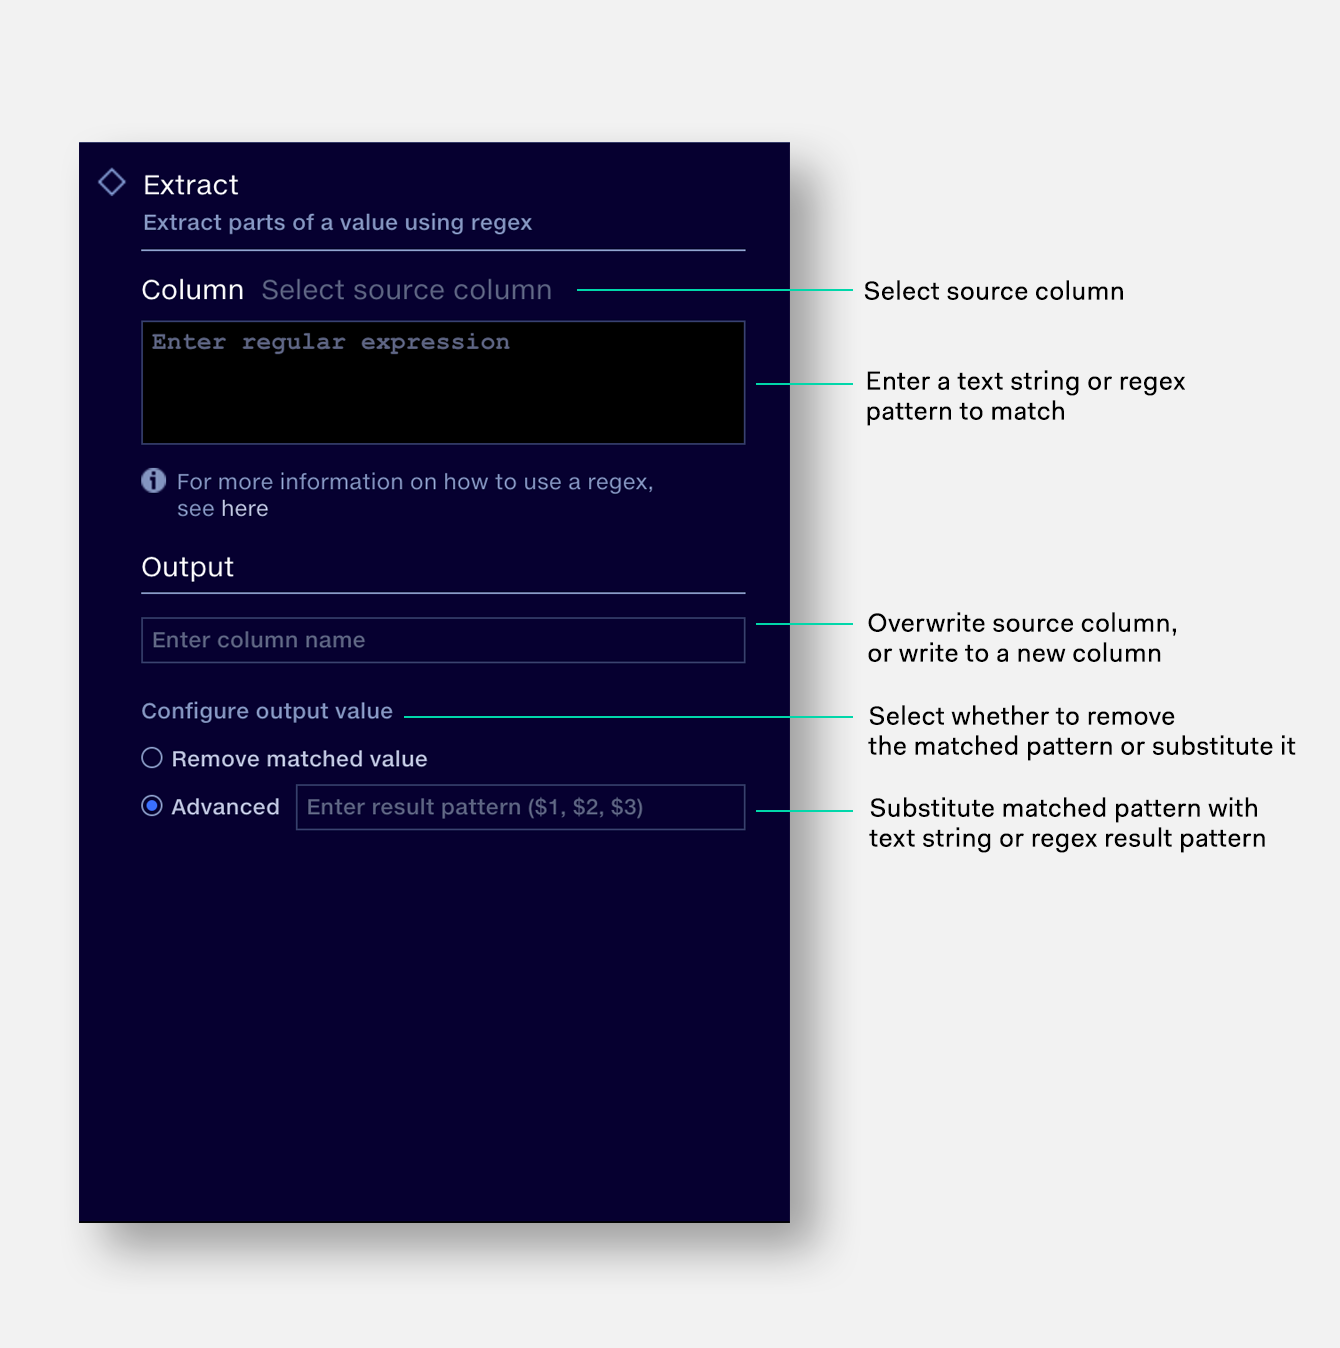
Column
Select the source column to search.
Regex
Enter the search term or regex pattern.
Output column
Either name a new output column, or select the source column to overwrite it. If no column name is entered, an unnamed column will be created.
Configure output
To remove regex matches, select ‘Remove matched value’.
To replace regex matches select ‘Advanced’ and enter a text string or a result pattern
(e.g. $1, $2, $3).
Search patterns
Enter the search pattern in the Regex field. This could be a specific sequence of text or numbers, such as the word ‘Rd’, though this is usually better dealt with using the Substitute function in Calculate.
The Regex operation is best used to search for patterns, using the Regular Expressions syntax. For example:
- .matches any character
- \dmatches any digit
- \wmatches any word character
- ( )matches groupings of characters
See the Syntax reference section for details and examples of the most commonly used Regex syntax.
Result patterns
Once a pattern has been matched, it can be either be removed, replaced, modified or repeated. The result can overwrite the source column or can be written to a new column. The $ symbol is used to reference groups within the regex pattern.
- Entering a simple text string, e.g. Roadwill overwrite all matches with the word “Road”.
- $1will write the first matched pattern. If no groups are defined, the whole match is written.
- abc$1will append “abc” to the start of the matched pattern.
- If the pattern contains multiple groups,$1references the first group,$2the second group, etc.
Examples
1. Extract any numbers at the start of a string
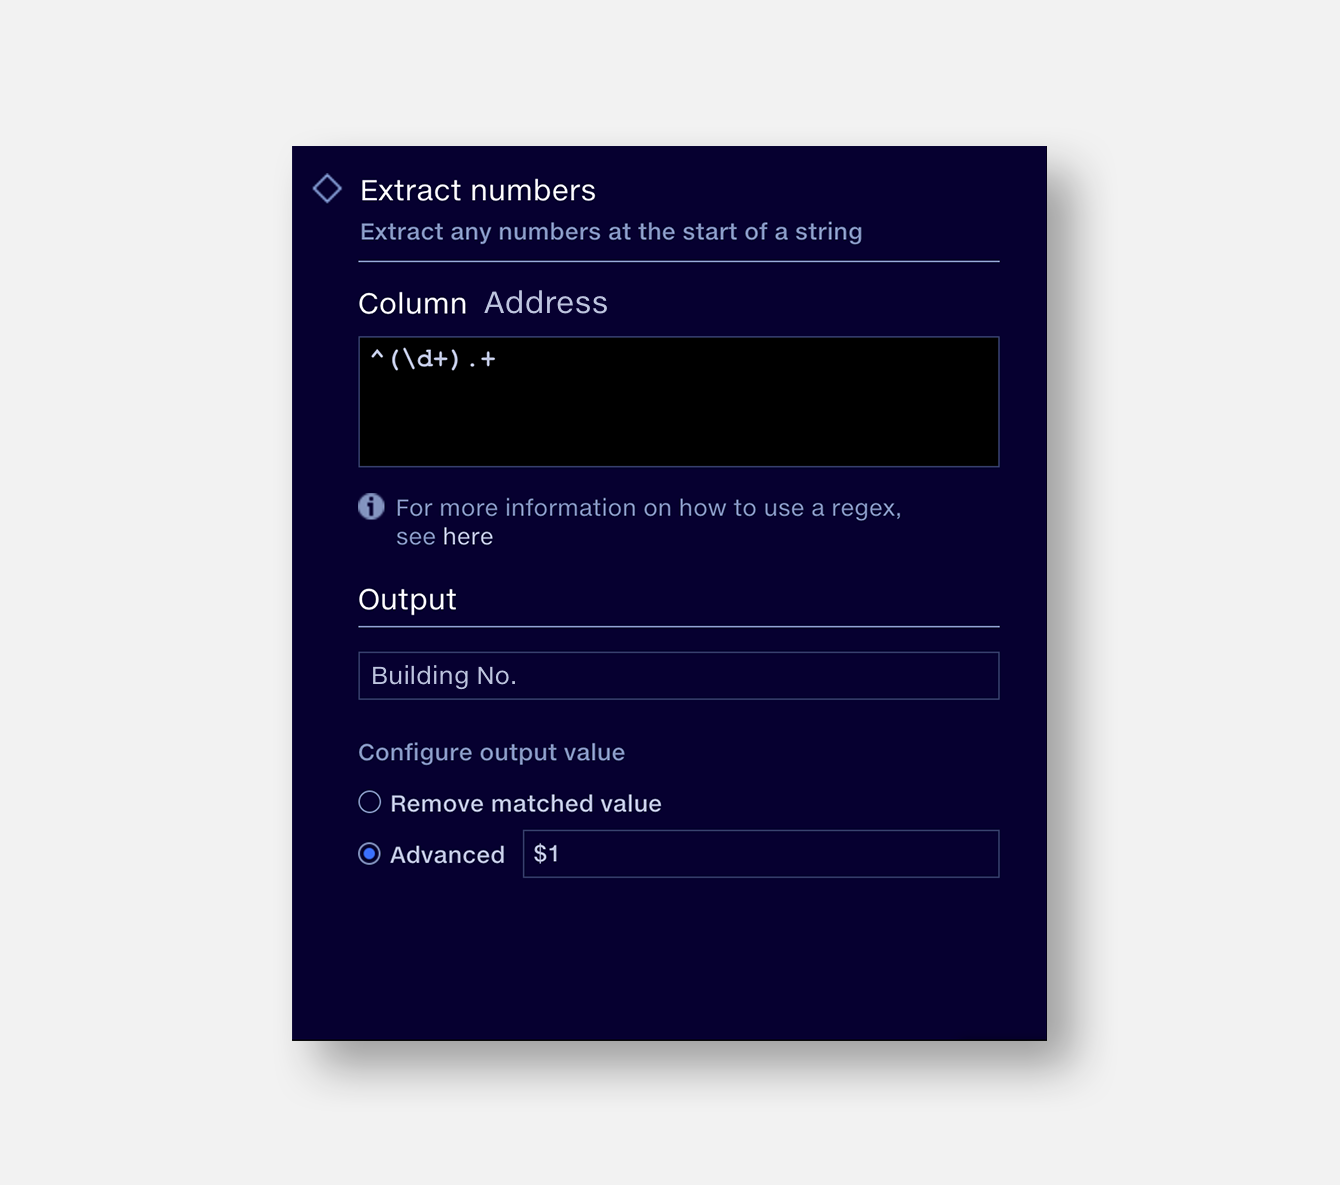
We want to find the building number from a column of addresses and extract it to a new column. We can do this by writing a regex to identify any sequence of numbers at the start of an address.
- Select the source column Address.
-
Enter a regex pattern:
^(\d+).+
anchors to the start of the string.^
looks for a sequence of digits of any length.(\d+)
indicates that the digits should be followed by any number of characters..+
- Output to a new column called Building No.
- Select ‘Advanced’ and enter the result pattern $1to write the matched patterns to the new column.
2. Remove non-alphanumeric characters
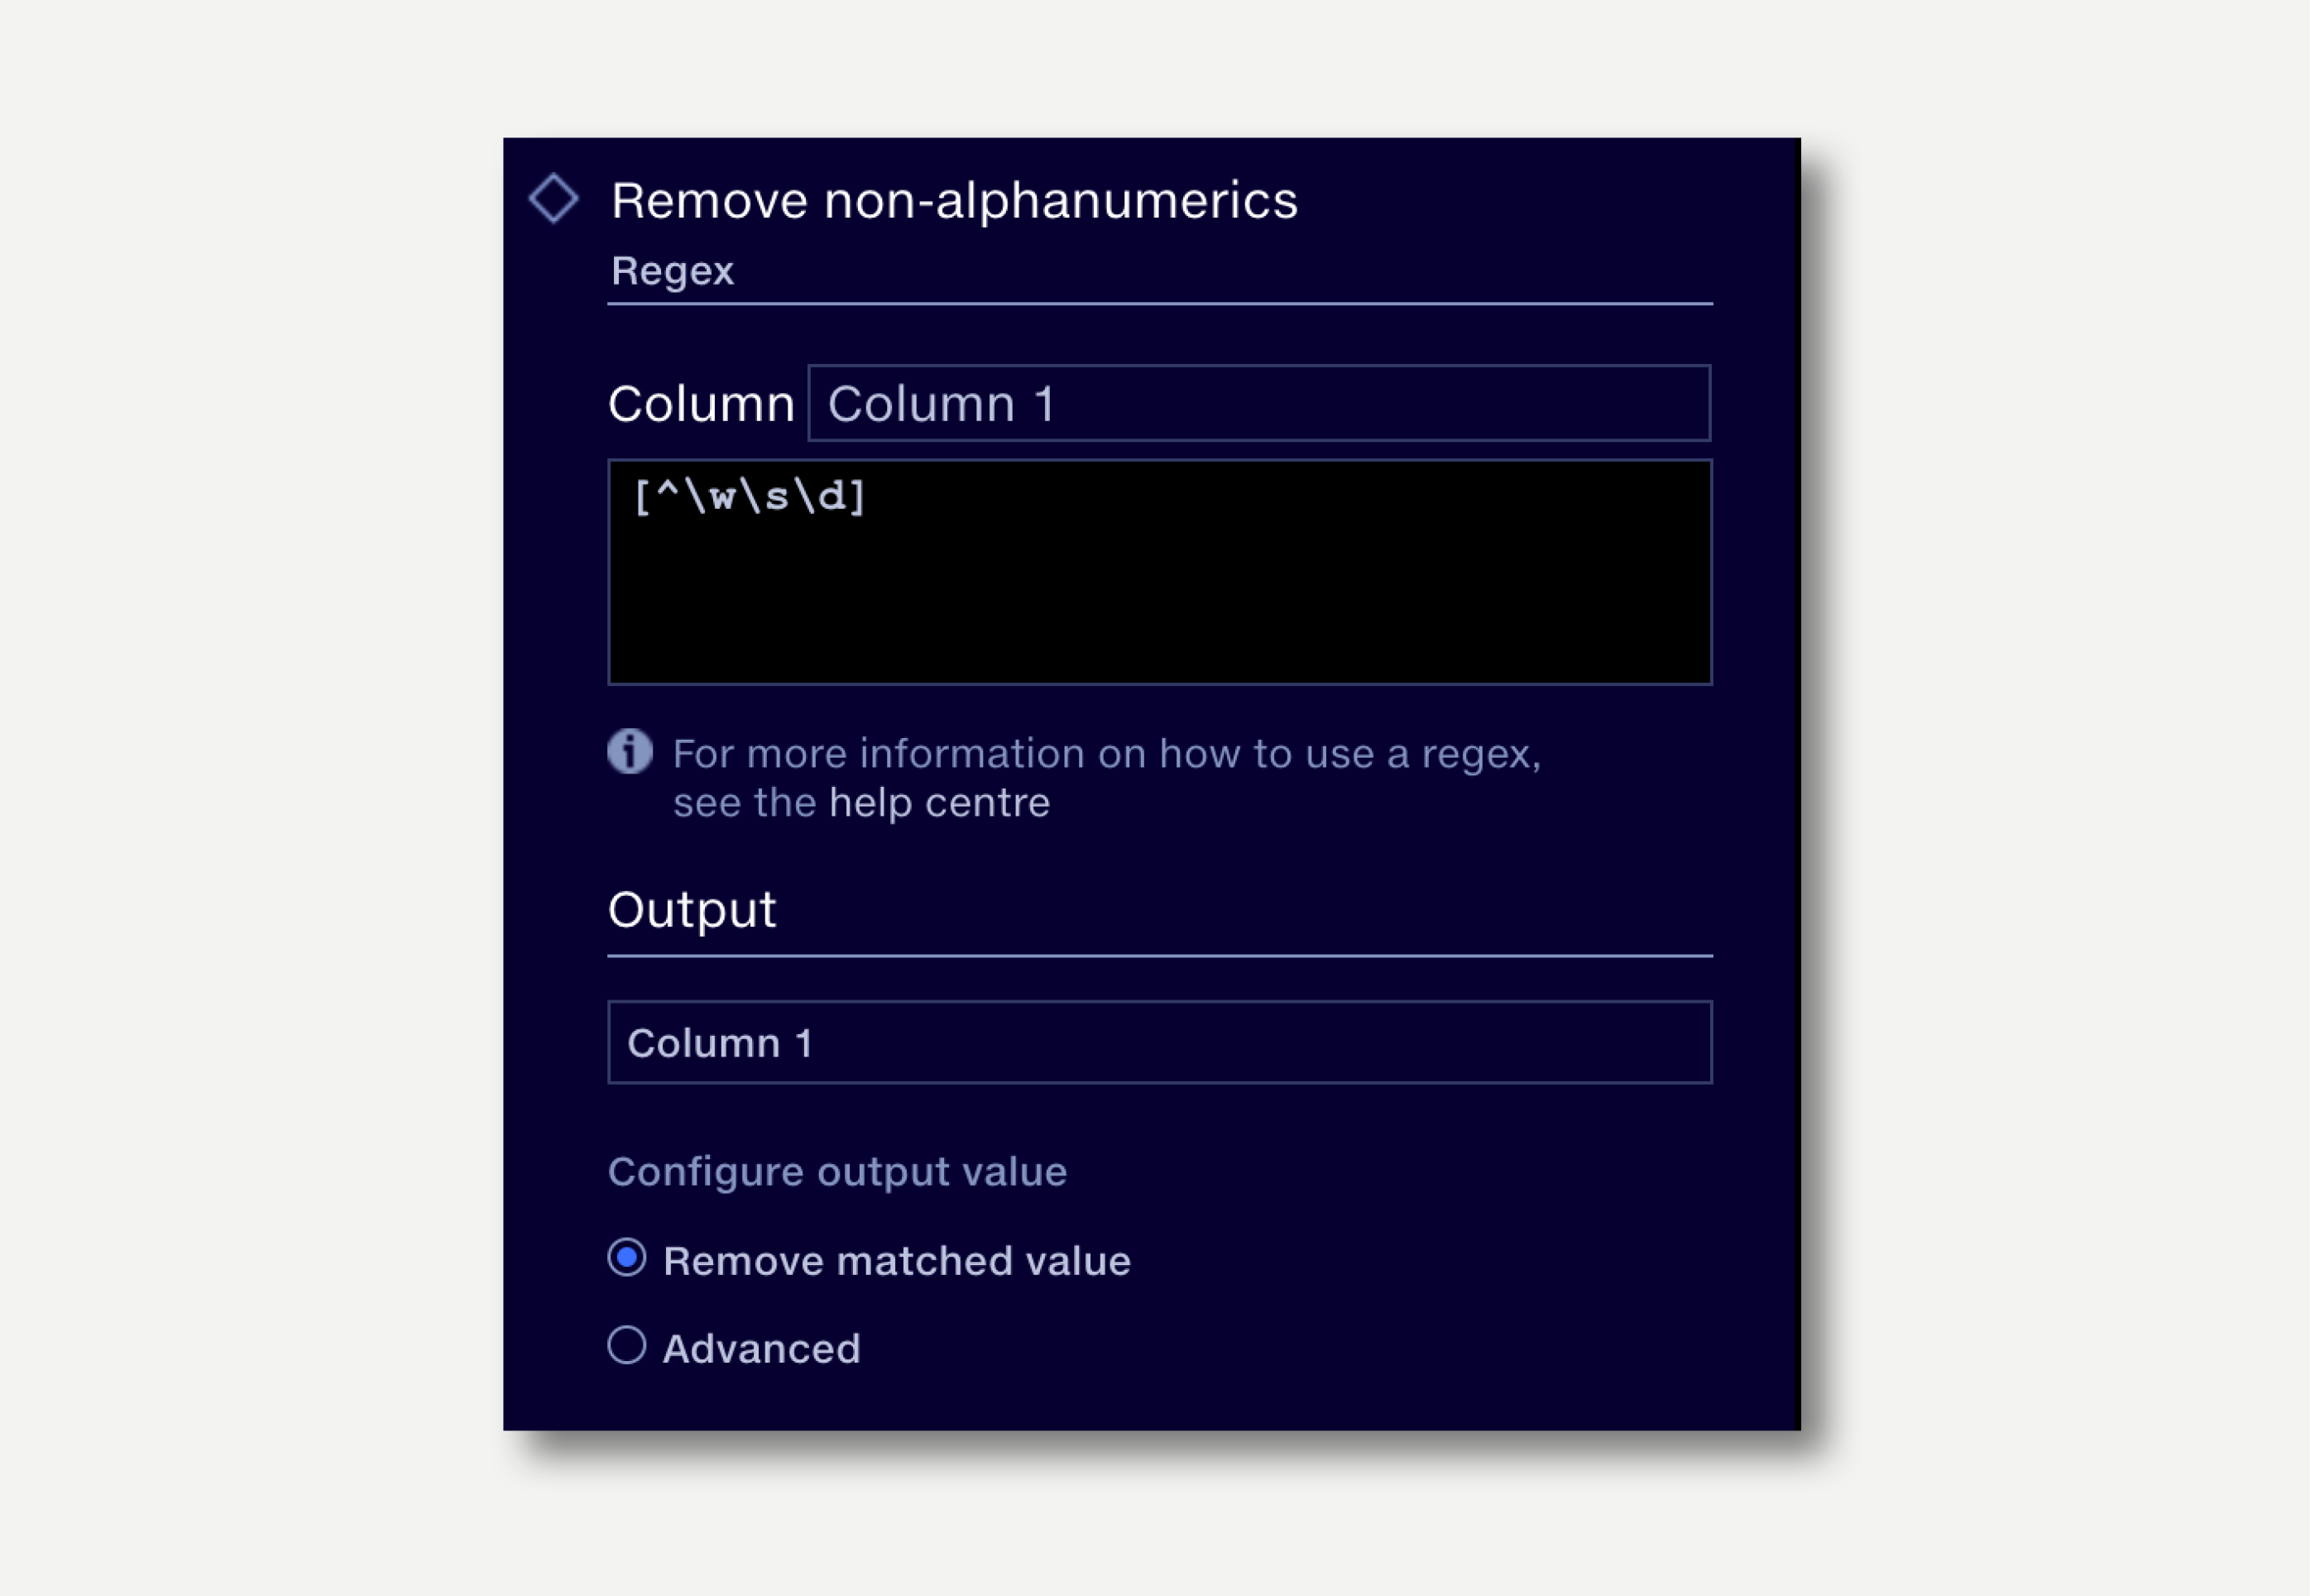
We want to strip out non-alphanumeric characters, such as punctuation or symbols, to help standardise a list of company names. This regex looks any characters that are not words, whitespaces or digits and removes them.
- Select the source column Column 1.
-
Enter a regex pattern:
[^\w\s\d]
matches characters not contained within the brackets[ ]
matches any word character\w
matches any whitespace character\s
matches any digit\d
- Select the output column Column 1to overwrite the original column.
- Select ‘Remove matched value’.
3. Combine initials
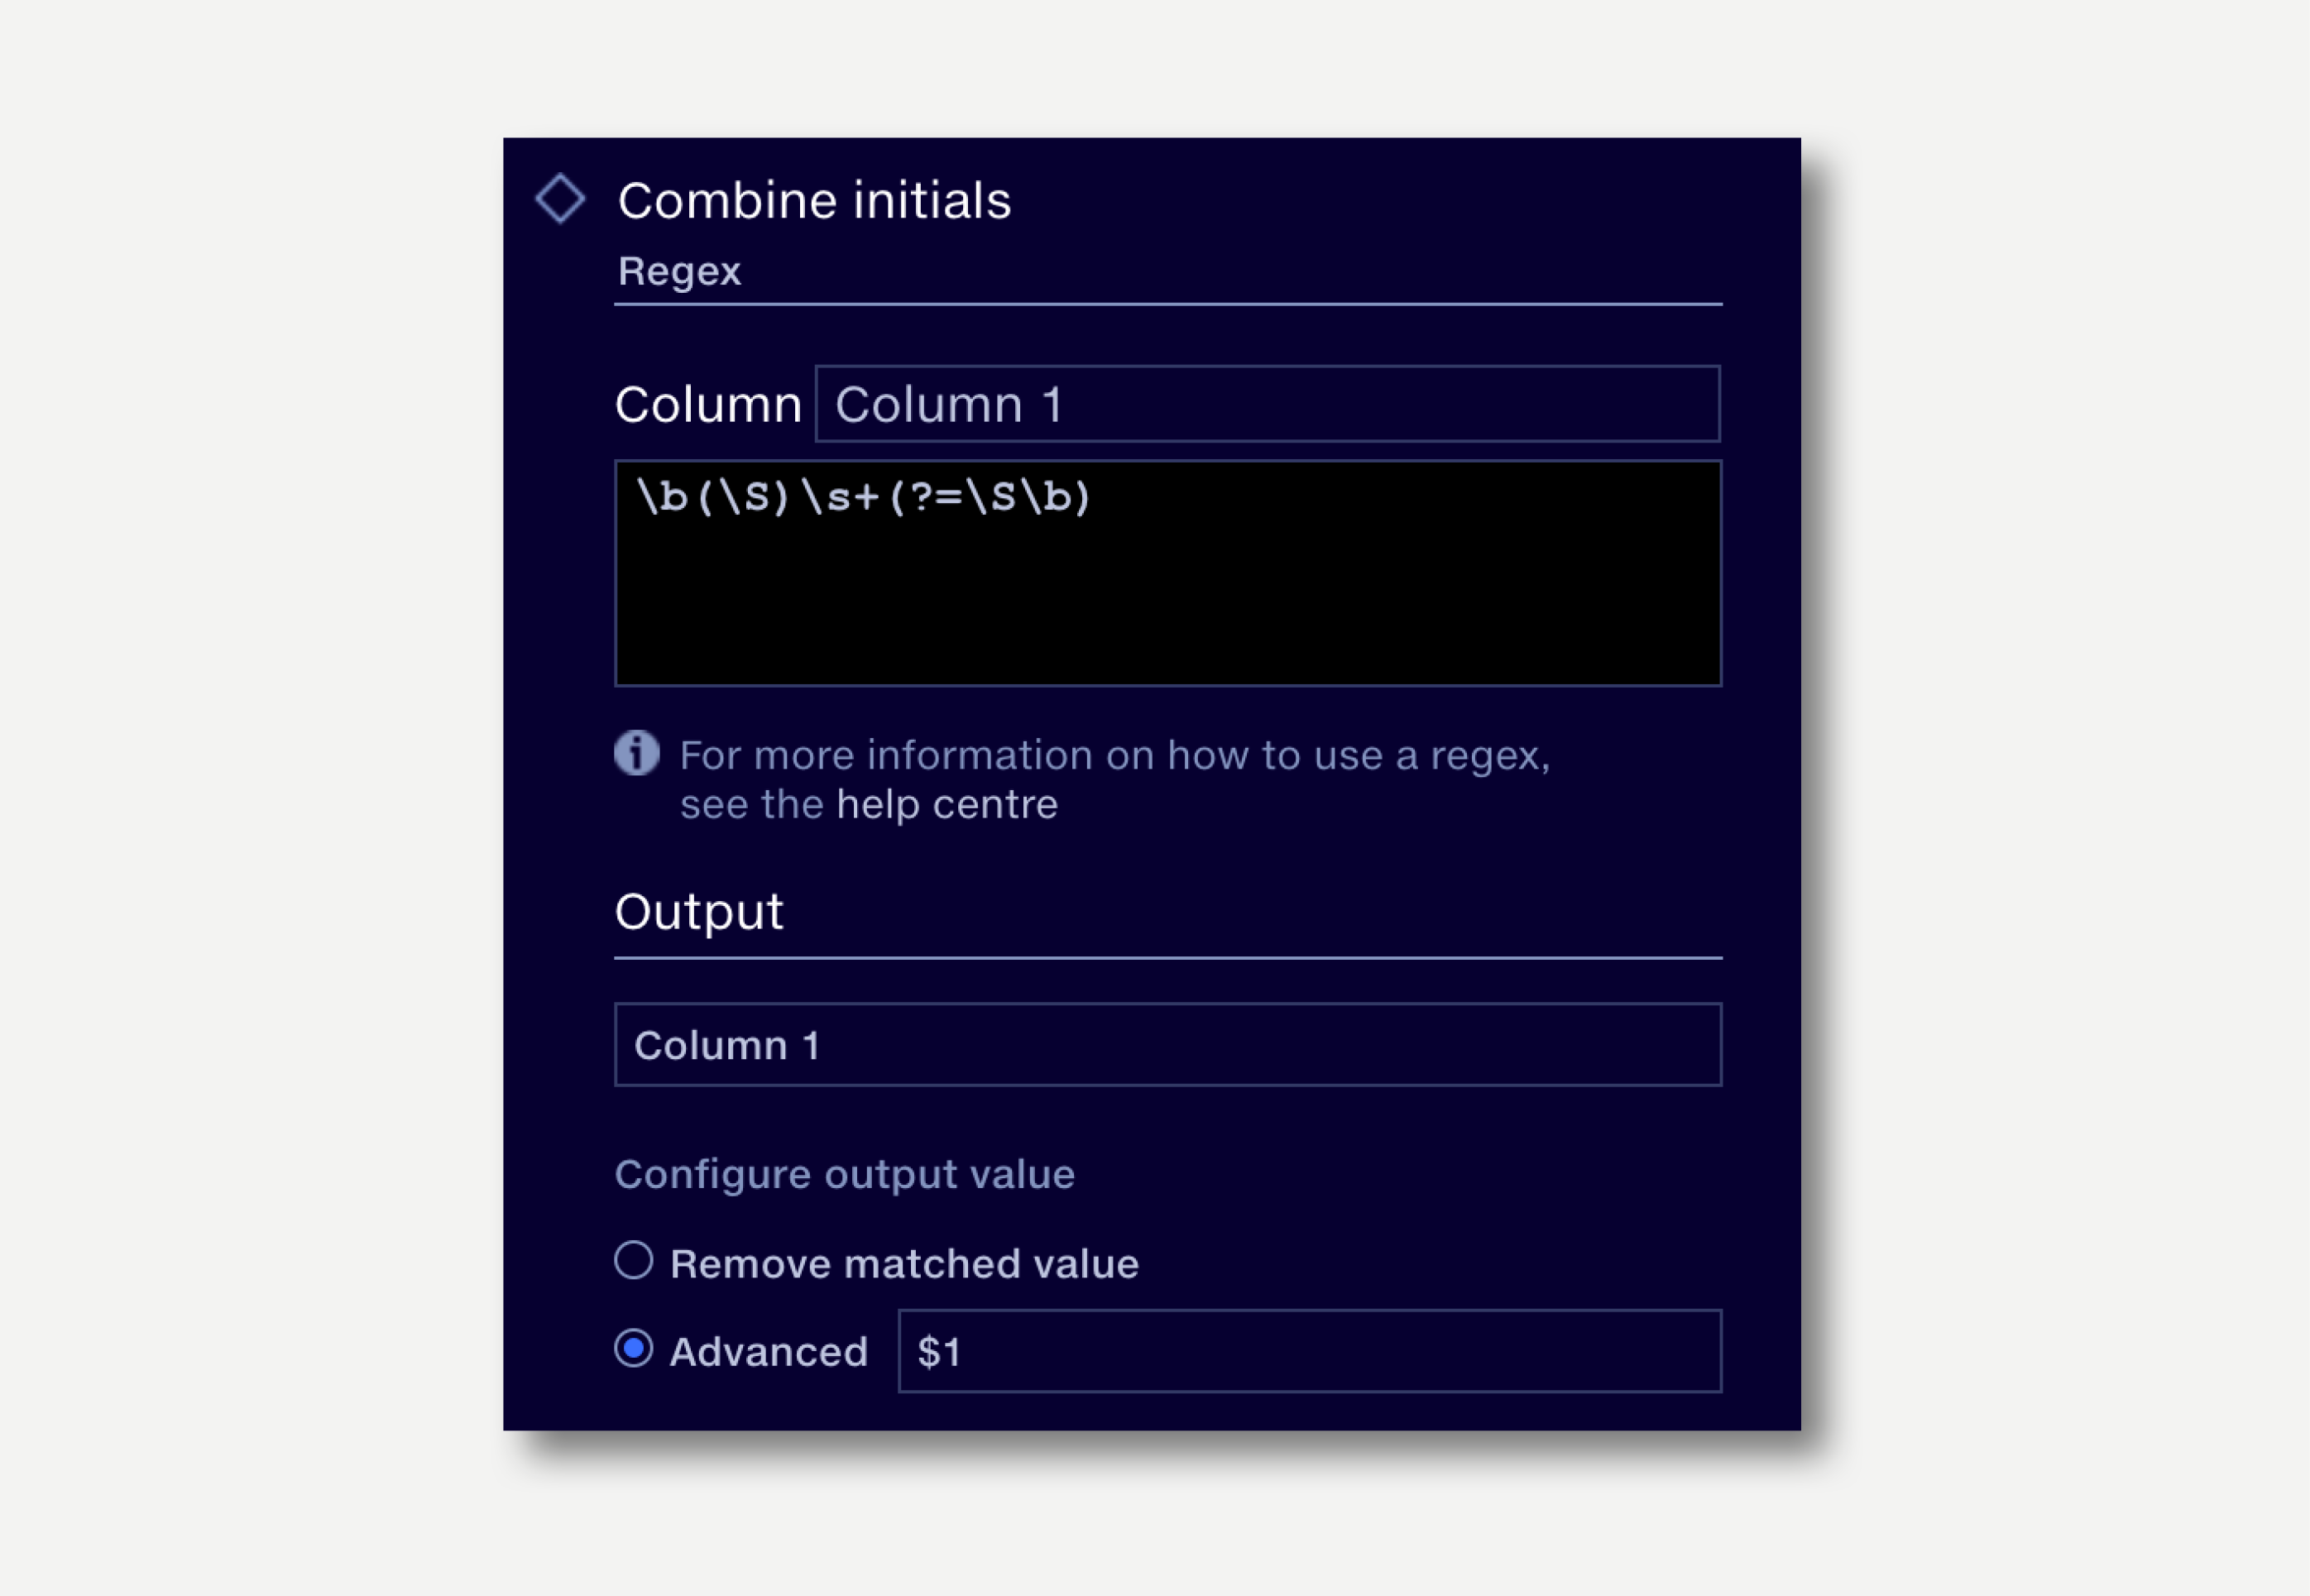
In a list of company names, where initials are separated by a space, we want to remove the space. This regex looks for a single non-whitespace character, followed by one or more spaces. It then writes only the matched non-whitespace characters followed by the rest of the string.
- Select the source column Column 1.
-
Enter a regex pattern:
\b(\S)\s+(?=\S\b)
asserts position at a word boundary\b
matches any single non-whitespace character and defines the capturing group(\S)
matches any whitespace character, one or more times\s+
Positive lookahead for a non-whitespace character at a word boundary. This marks the start of the rest of the string.(?=\S\b)
- Select the output column Column 1to overwrite the original column.
- Select ‘Advanced’ and enter the result pattern $1to write the matched non-whitespace characters, followed by rest of the string, to the original column.
Syntax reference
Quantemplate uses the Java version of regex. For full syntax details see the Java Regex Documentation.
CharacterFunctionExample|Or
Matches either the expression before or the expression after|gray|greymatches either “gray” or “grey”( )Groupinggray|greyandgr(a|e)yboth match “gray” or “grey”[ ]Matches a single character thatiscontained within the brackets[abc]matches “a”, “b”, or “c”
gr[ae]ymatches “gray” or “grey”, but not “graey”, “graay”, etc.
[a-z]specifies a range which matches any lowercase letter
from “a” to “z”
[abcx-z]matches “a”, “b”, “c”, “x”, “y”, or “z”
[hc]atmatches “hat" and “cat”
[a.c]matches only “a”, “.”, or “c”
[^ ]Matches a single character thatis notcontained within the brackets[^abc]matches any character other than “a”, “b”, or “c”
[^a-z]matches any character that is not a lowercase letter
from “a” to “z”
[^b]atmatches all strings matched by .at except “bat”
q[^x]matches “qu” in “question”. It does not match “Iraq” since there is no character after the q for the negated character class to match
{n}Preceding item is matched exactly n timesa{3}matches only “aaa”
[1-9][0-9]{3}matches a number between 1000 and 9999
{min,}Preceding item is matched min or more timesa{3,}matches “aaa”, “aaaa”, “aaaaa”, “aaaaaa”, etc.
a{3,5}matches “aaa”, “aaaa” and “aaaaa”
{min,max}Preceding item is matched at least min times, but not more than max timesa{3,5}matches only “aaa”, “aaaa” and “aaaaa”.
[1-9][0-9]{2,4}matches a number between 100 and 99999
.Matches any charactera.cmatches “abc”, “acc”, “adc”, etc.
gr.ymatches “gray”, “grey”, “gr%y”
.atmatches any three-character string ending with “at”, including “hat”, “cat”, and “bat”
?Matches the preceding characterzero or onetimesab?cmatches “ac”, “abc”
colou?rmatches “color” and “colour”
[hc]?atmatches “hat”, “cat”, and “at”
*Matches the preceding characterzero or moretimesab*cmatches “ac”, “abc”, “abbc”, “abbbc”, etc.
s.*matches “s” followed by zero or more characters, for example: “s” and “saw” and “seed”
[hc]*atmatches “hat”, “cat”, “hhat”, “chat”, “hcat”, “cchchat”, “at”, etc.
+Matches the preceding characterone or moretimesab+cmatches “abc”, “abbc”, “abbbc”, but not “ac”
[hc]+atmatches “hat”, “cat”, “hhat”, “chat”, “hcat”, “cchchat”, etc. but not “at”
^Anchors thestartingposition in a string^[hc]atmatches “hat” and “cat”, but only at the beginning of the string
$Anchors theendingposition in a string[hc]at$matches “hat” and “cat”, but only at the end of the string
\Escaped
Treats the escaped character as a literal rather than a regex command\[.\]matches any single character surrounded by “[” and “]” since the brackets are escaped, for example: “[a]” and “[b]”
1\+1=2matches “1+1=2”
Character classes
CharacterFunction\dAny digit\DNot a digit\wAny word character (Alphahnumeric characters, plus the underscore “_”)\WNot a word character\sWhitespace character (tab, carriage return, space, etc.)\SNot a whitespace\AFirst character in a string\zLast character in a string\uUppercase letters\lLowercase letters\pVisible characters and the space character\bWord boundaries\BNon-word boundaries
Characters
CharacterFunctionxThe character x\\The backslash character\tThe tab character\rThe carriage-return character\eThe escape character
Resources
Regex101.com
Easy-to-use syntax testing environment for regular expressions.Java Regex Documentation
Full documentation of the Java Regex version used by Quantemplate.Java Regular Expressions Tester
Another environment to test the validity and output of a regular expression, including output group replacement functionality. - Select the source column