Map Column Headers
In this section
Overview
The Map column headers operation takes source files with differing header schemas and maps them to a unified header schema. This allows the datasets to be unioned and treated identically by downstream operations.
For example, you may have three source files, each with a column of policy numbers, but named differently in each dataset: Policy Number, Pol. #, Policy Num. These column names can be mapped to a common ‘Policy Number’ field.
A typical workflow incorporating column mapping would be:
- Import datasets
- Define the data area within each dataset using Remove Rows and Detect Headers
- Map the column headers to a single schema using Map Column Headers
- Union the datasets together
Additionally, columns in the output dataset can be added, removed or re-ordered, and empty or missing columns in the source data populated with text or numbers.
Data semantics and column mapping
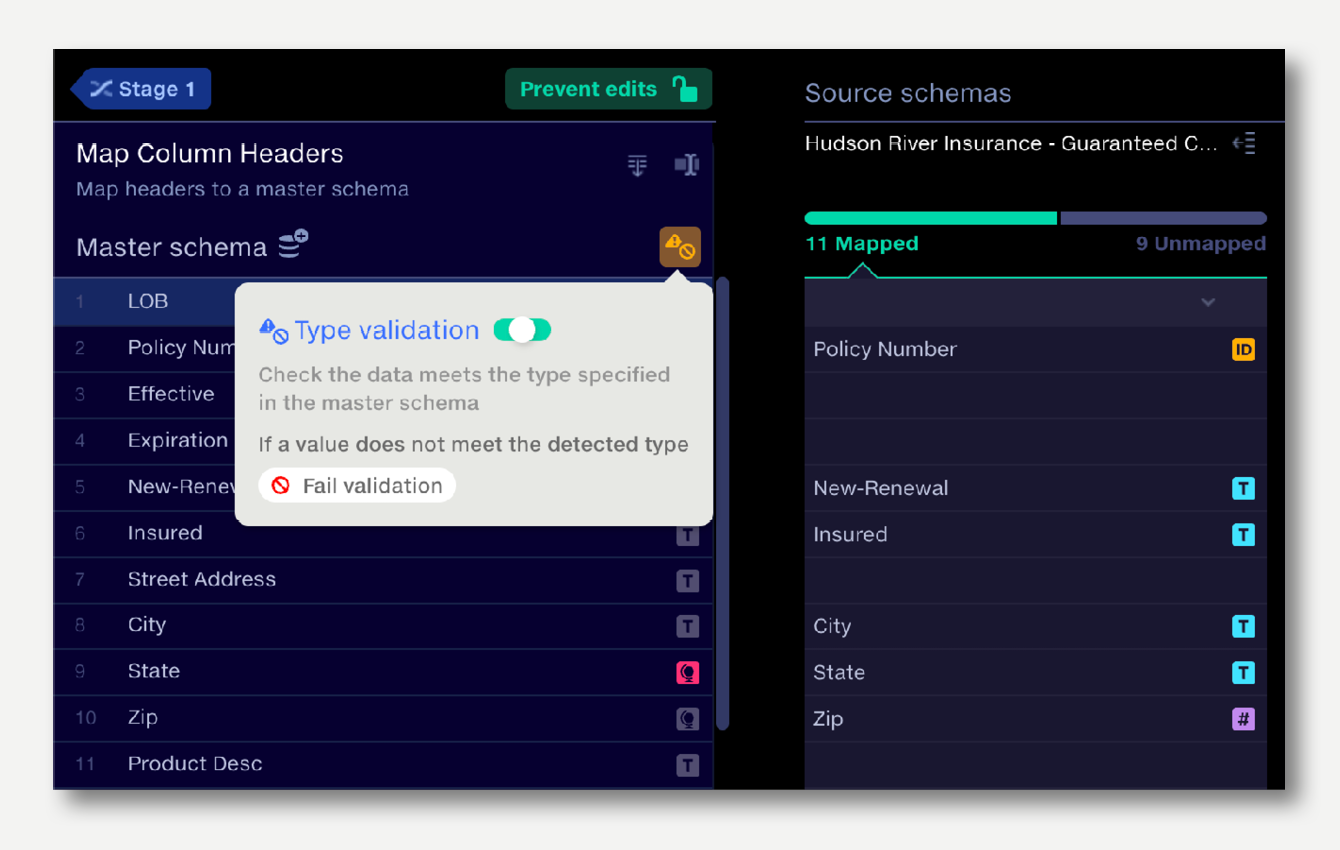
Whenever you create or import a dataset to Quantemplate, the contents of every column is analysed, identifying its semantic type. This is used in Map Column Headers to weight mapping suggestions, and also for data type validation.
See Data Semantics to learn more about typing and profiling, and Data Type Validation to see how to apply automated type validations within Map Column Headers.
Workspace
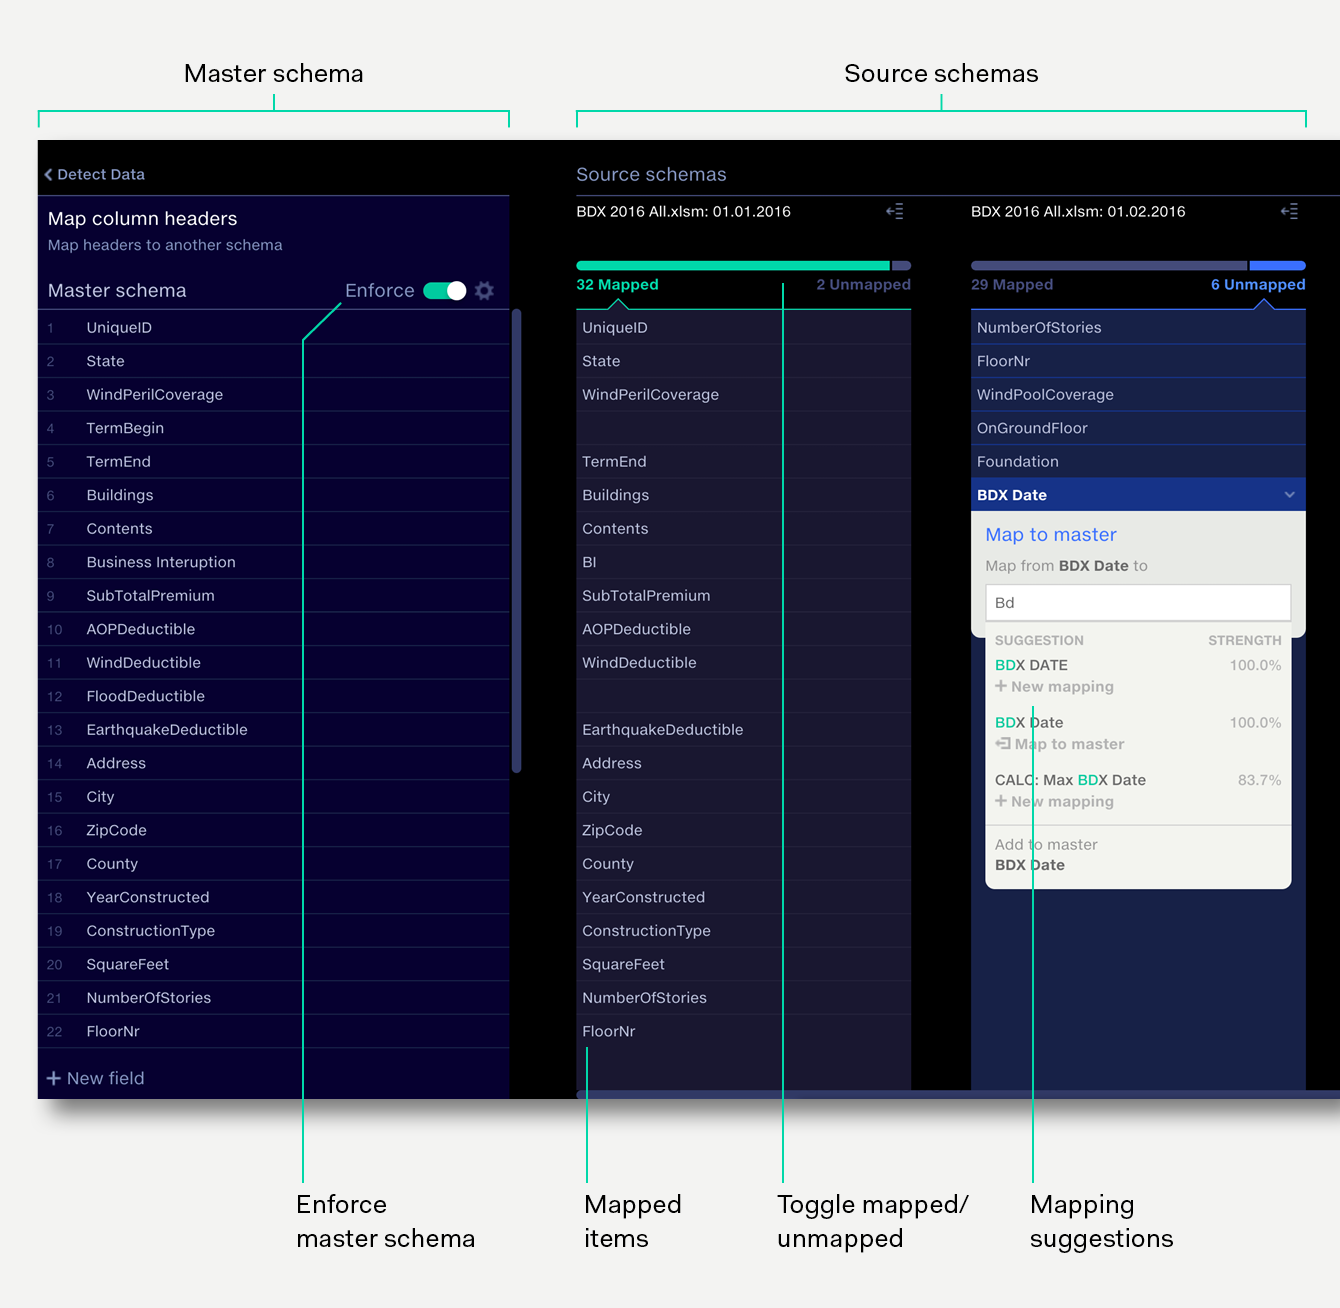
Master Schema
List of columns in master schema.
Source Schemas
Lists of columns in source schemas. Horizontal position of mapped items indicates their mapping to the master.
Mapped items
The layout shows each column mapping across the source schemas and the master schema horizontally, making it very quick to visually deduce the mapping structure across all your sources.
Toggle mapped/unmapped
Toggle between mapped and unmapped items.
Rename only mode
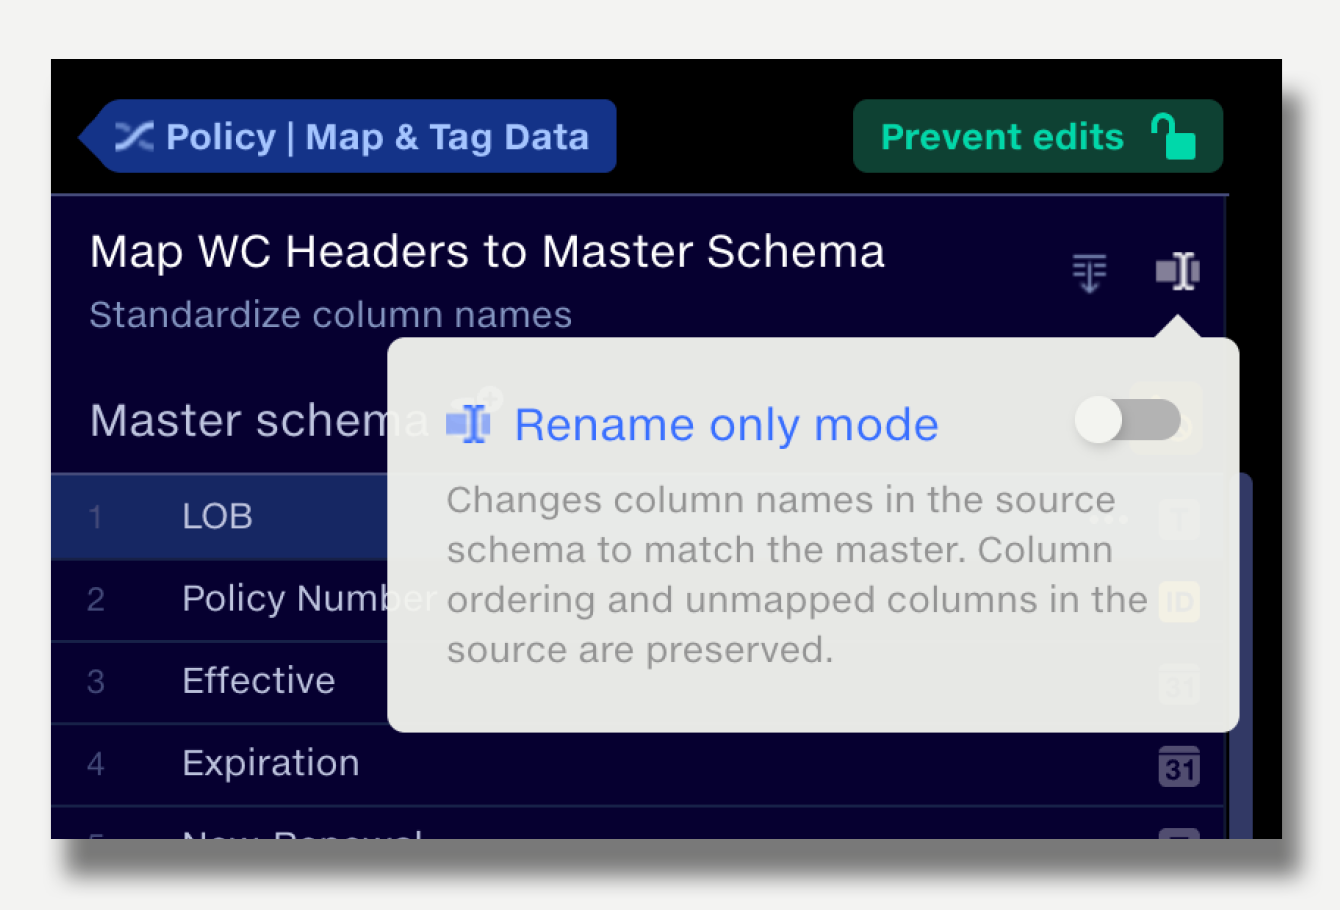
Switch between a mode which enforces the exact master schema, or a mode which only renames mapped headers names. See Rename Only mode.
Mapping suggestions
Clicking on an unmapped item suggests mappings in the master schema, alongside suggestions for new mappings.
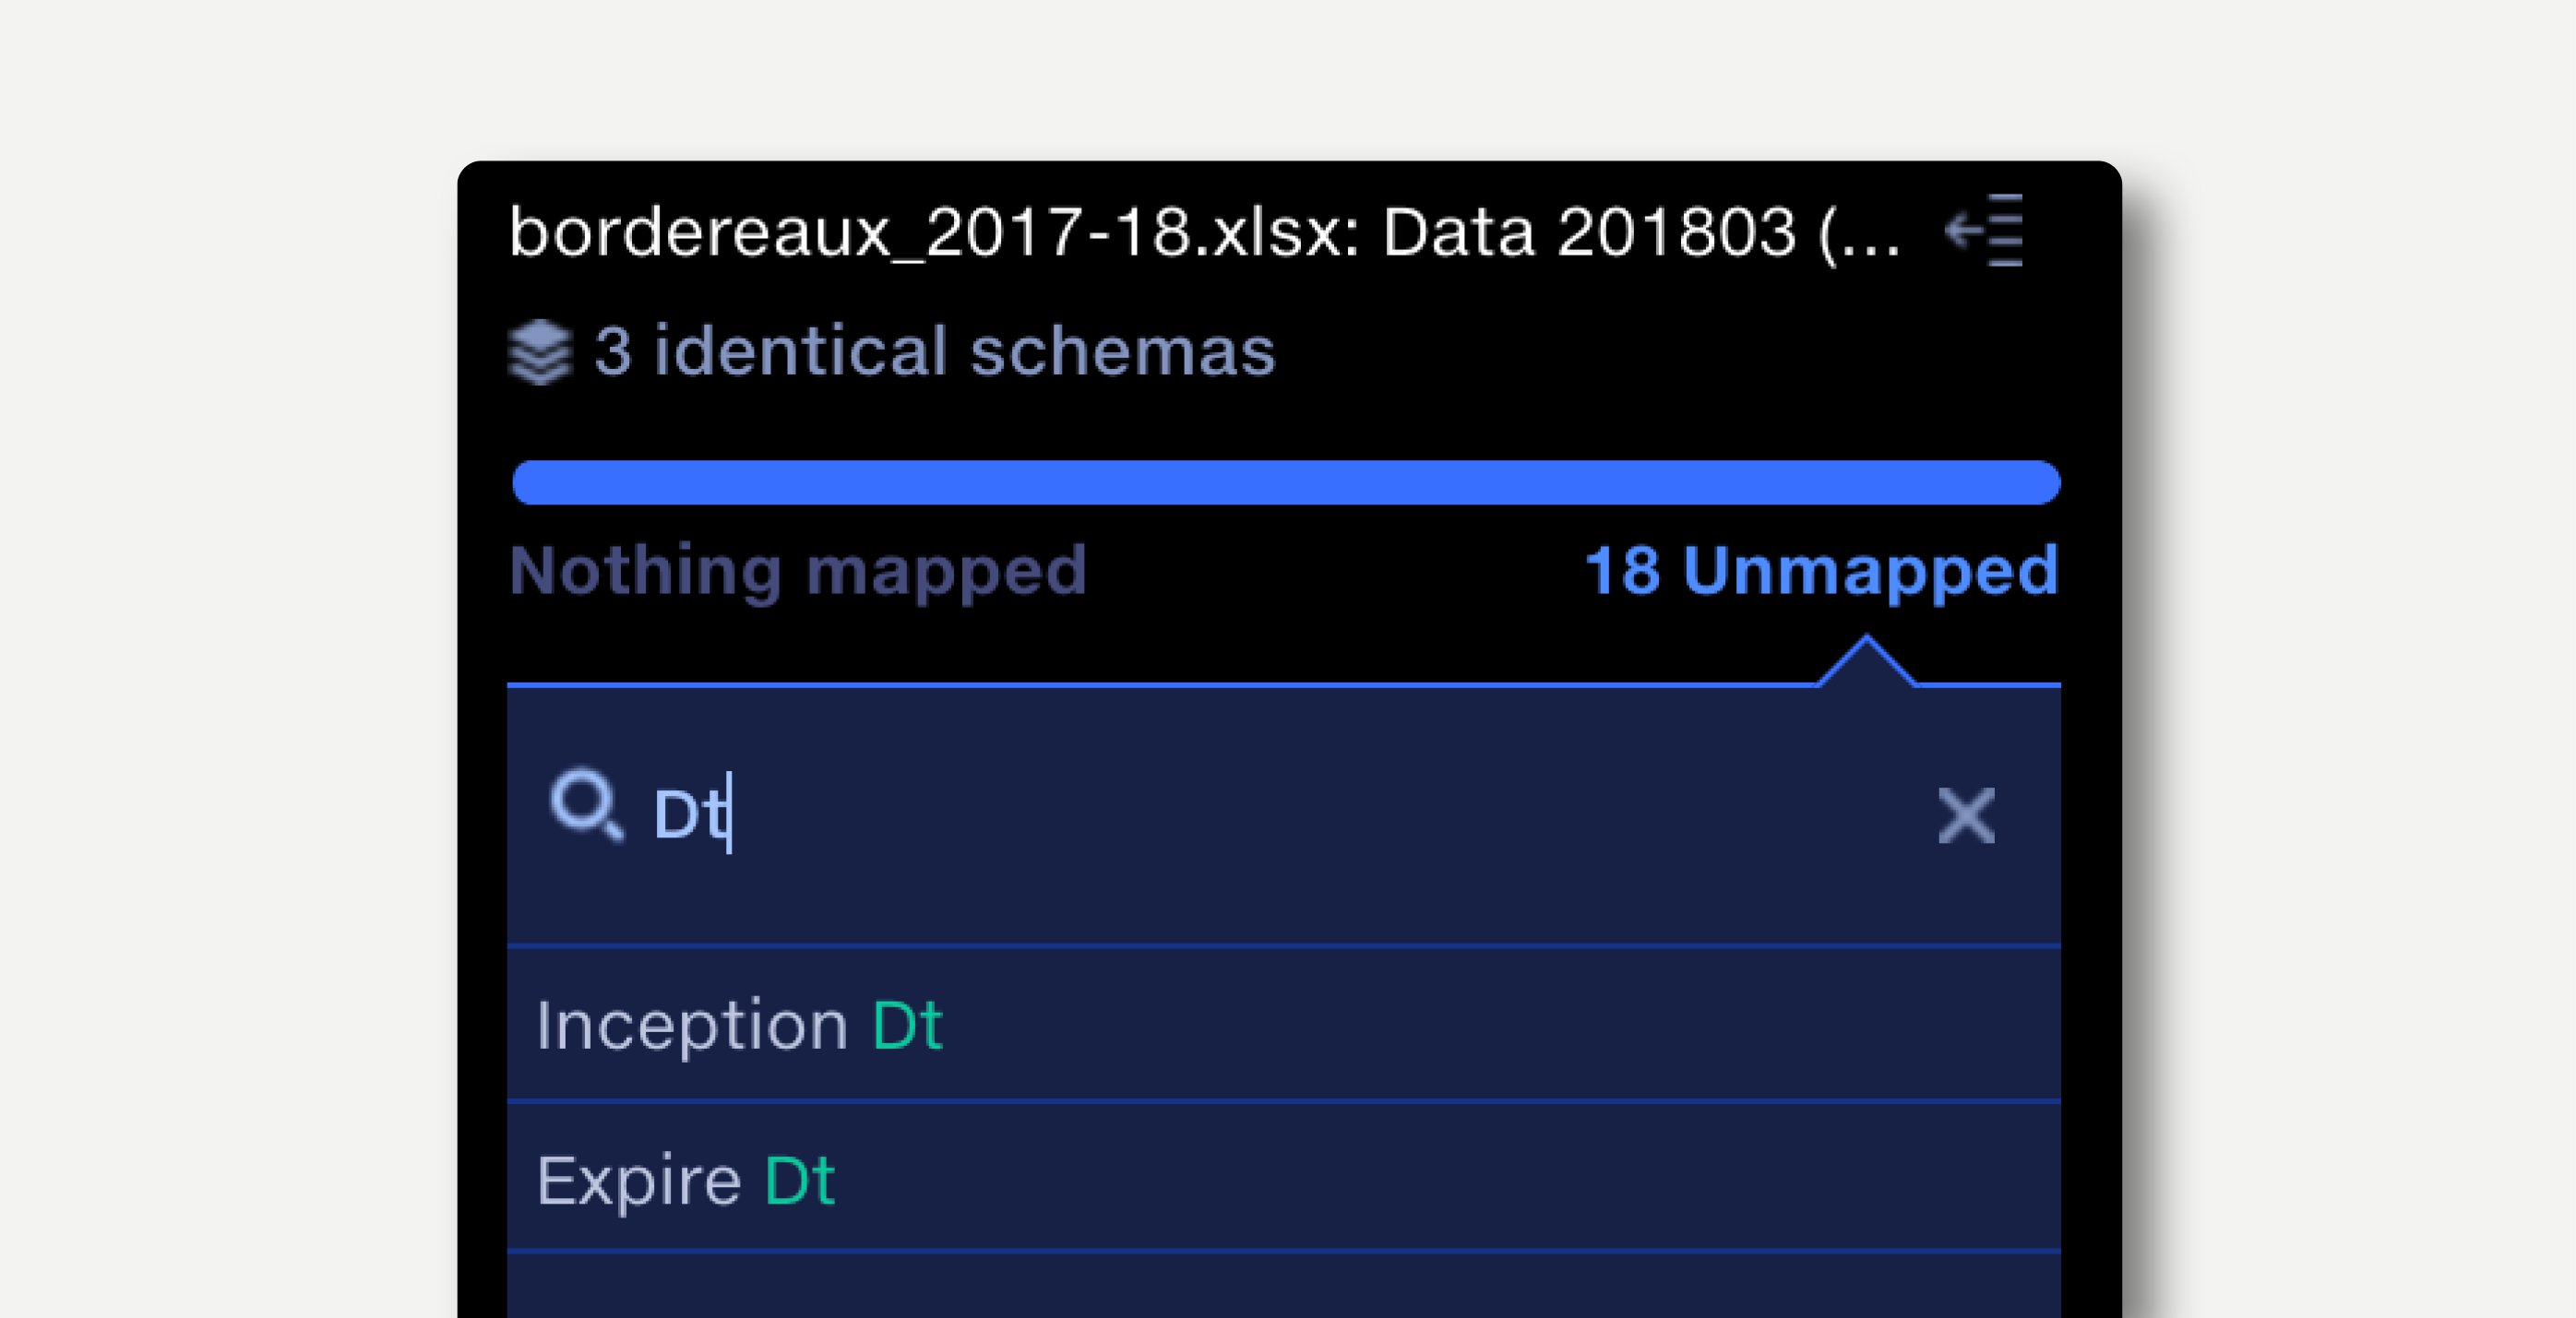
Search unmapped items
Click the search bar at the top of an unmapped schema to search unmapped items within an input.
Mapping to a schema
Initial view
On opening the operation, the initial view shows the distinct column structures across the input files to the operation, with no master schema or mapping defined.
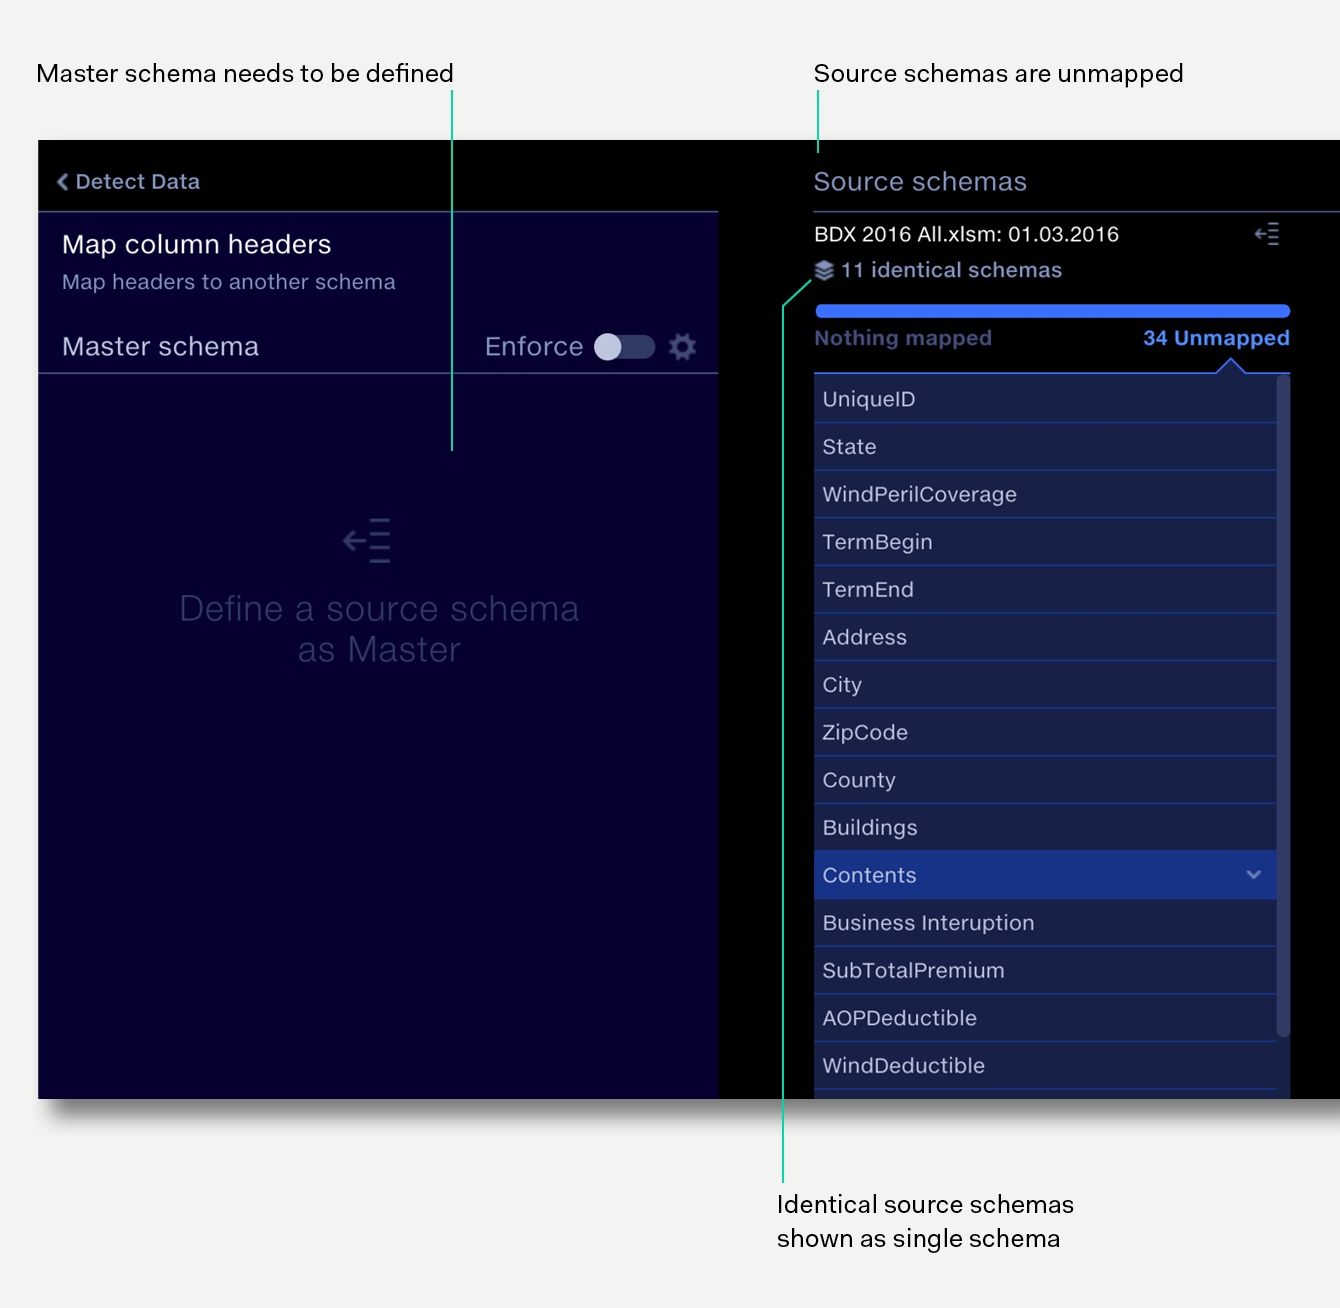
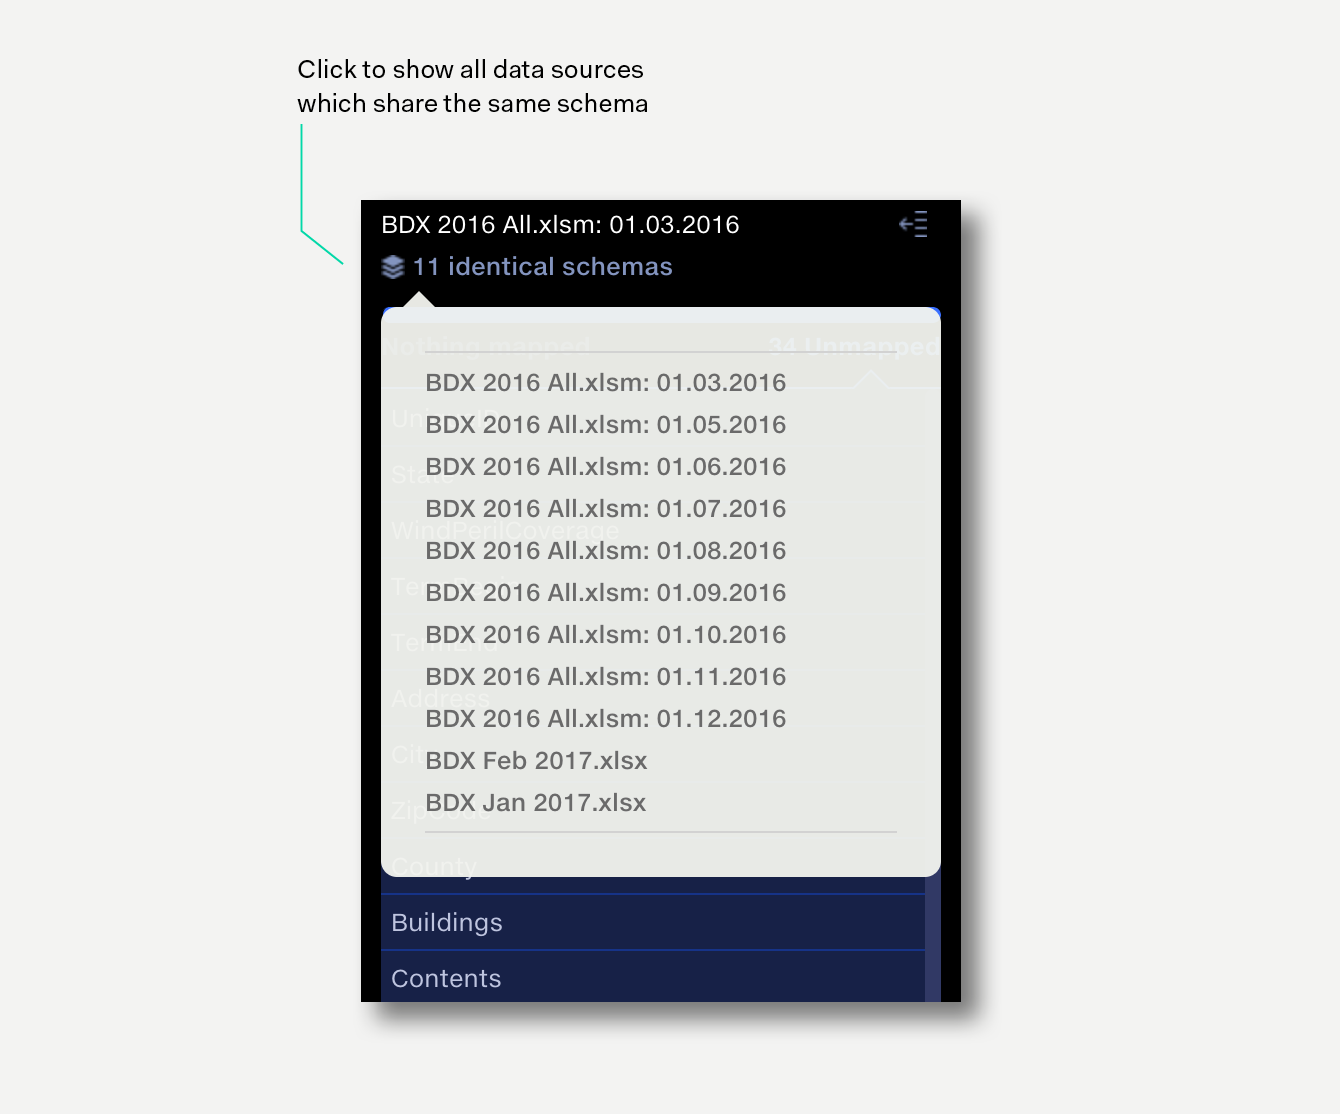
If there are multiple input files that have identical column structures, then Quantemplate will stack these together, so that only distinct columns structures are displayed. To see which input files to the operation are stacked in each distinct column structure, hover over the file name at the top of the column.
Defining the master schema
Define a master schema from the data dictionary
To define a master schema from your data dictionary (data repo), click the 'Select dataset' button in the master schema panel. Selecting a dataset that contains all the column headers you wish to map to, plus a few rows of data, will import that dataset's headers and semantic types.
If a master schema has already been defined, click on the dataset icon next to the label 'Master Schema' to select a different one.
Define a source schema as a master
Another way to define a master schema is to define it from one of the source file schemas, and then to map any remaining column headers from the other source schemas to the master.
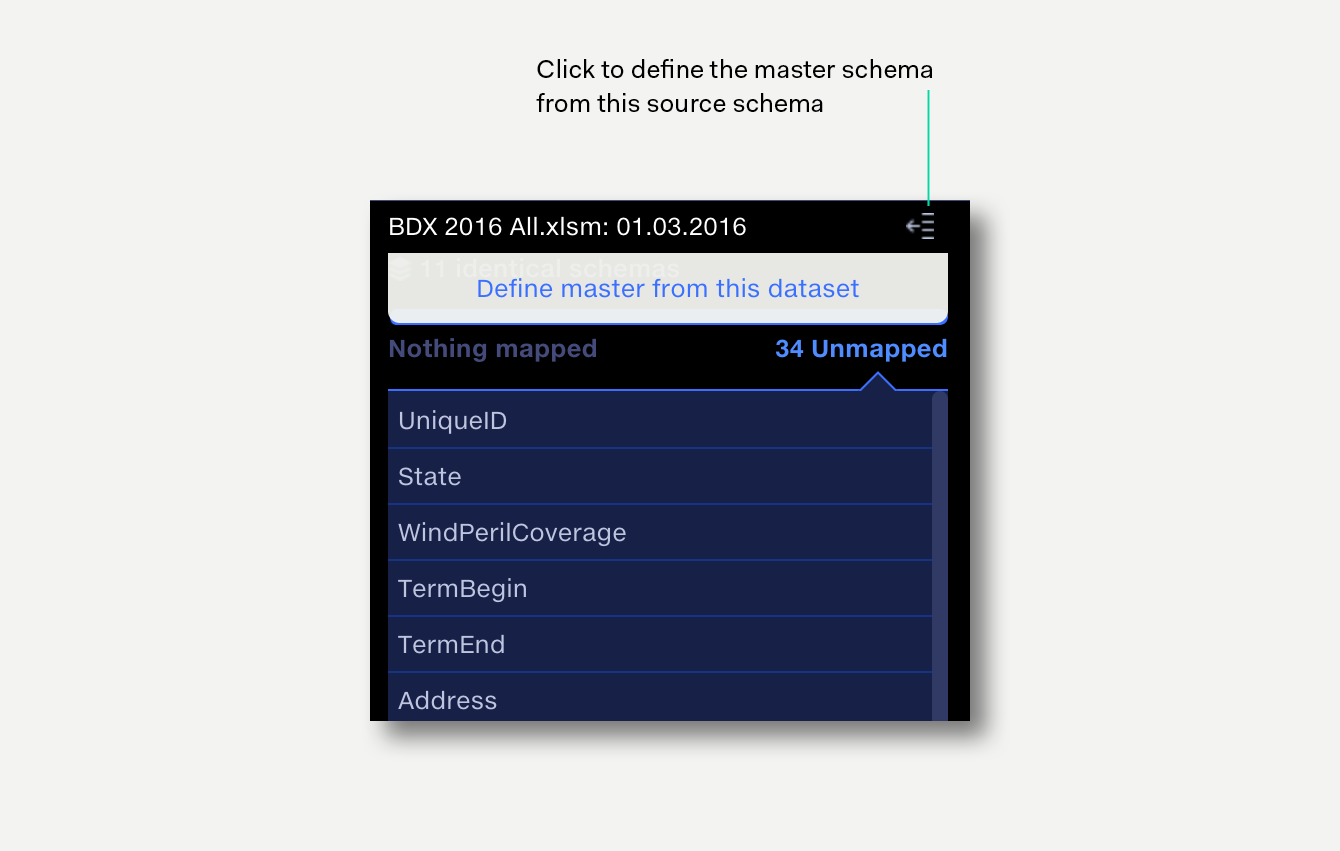
Click on Define master from this dataset for the file schema that you wish to use as a starting point for the master schema template. This will instantly:
- Define the selected source schema as the master
- Map all of the column headers in that schema to the corresponding columns in the master schema.
- Maps columns in the other source schemas that have the same name as the columns in the master schema. The column name is case-insensitive in the mapping.
Map individual fields
Rather than taking a whole source schema as a starting point, individual fields can be mapped in from one or more source schemas. See Mapping in source files below.
Manually enter fields
Alternatively a master schema can be created from scratch by manually entering fields. To add a new field, click the New field button at the bottom of the master schema, enter the field name and hit return (↵).

Mapping in source files
To view unmapped fields in a source schema click on the Unmapped toggle. Clicking on an unmapped item reveals mapping suggestions.

Map to master will map the source field to an existing column header in the master schema.
New mapping appears under suggestions that are not in the master schema, and will create a field in the master schema and map the source item to it.
Add to master will take the exact name of the source column and add it to the master schema as a new field.
The strength rating indicates Quantemplate’s statistical confidence level in the suggested mapping.
Changing mappings
You can unmap, remap or replace currently mapped column headers.
To see the column headers that are currently mapped for a given schema, click on the Mapped toggle. Clicking on a Mapped toggle. Clicking on a mapped item reveals mapping suggestions.

Unmap
Unmap the item from the master schema. Item returns to the unmapped column.
Remap
Remap the item to a different available item in the master schema. Master items that have items from this source schema already mapped to them are not available.
Replace
Replace the item with one of the unmapped items in the source.
Populate
Fields in the source can be populated with a data value or text, if that column does not exist in a source schema. Rename Only mode should be disabled for Populate to apply. See Populating source fields below.
Rename only mode
Column mapping has two modes: the default enforces the structure of the master schema, whilst Rename Only mode will only rename columns.
Default behaviour
Schemas of output datasets will match the master schema exactly.
- Mapped source column names will be changed.
- Unmapped source columns will be removed.
- Column order of output files match the master.
- Columns can be populated with values.
Rename only mode
Output dataset headers are renamed, schema structure remains the same.
- Mapped source column names will be changed to match the master.
- Unmapped source columns will be output unchanged.
- Column order of output files will be unchanged from the order in the source.
Example
For a given source:
|
Source schema
|
|---|
|
Client name
|
|
Ref. no.
|
|
City
|
|
State
|
|
Country
|
Apply the following mappings:
|
Mappings
|
||
|---|---|---|
|
Client name
|
maps to
|
Client
|
|
Country
|
maps to
|
Territory
|
|
Ref. no.
|
maps to
|
Ref. no.
|
Outputs when Rename Only mode is enabled / disabled:
|
Output options
|
|
|---|---|
|
Rename Only off
|
Rename Only on
|
|
Client
|
Client
|
|
Territory
|
Ref. no.
|
|
Ref. no.
|
City
|
|
State
|
|
|
Territory
|
Adding new inputs
Default column mapping rules
Where a master schema has been defined and a new input is added to the stage, the operation will apply the following default mapping rules:
- If the new input matches an existing schema, then the columns in the new input will be mapped identically to that schema.
- If the new input doesn’t match an existing schema, then each column will be mapped to a matching column name in the master schema. Note that column name matches ignore differences in capitalisation.
A yellow warning will be shown in the stage panel if, after applying the above rules:
- There remain entries in the master schema without a mapped column from the new input.
- There remain entries in the new input that are unmapped.
Once the mappings have been reviewed in the column header mapping operation the warning will be removed.
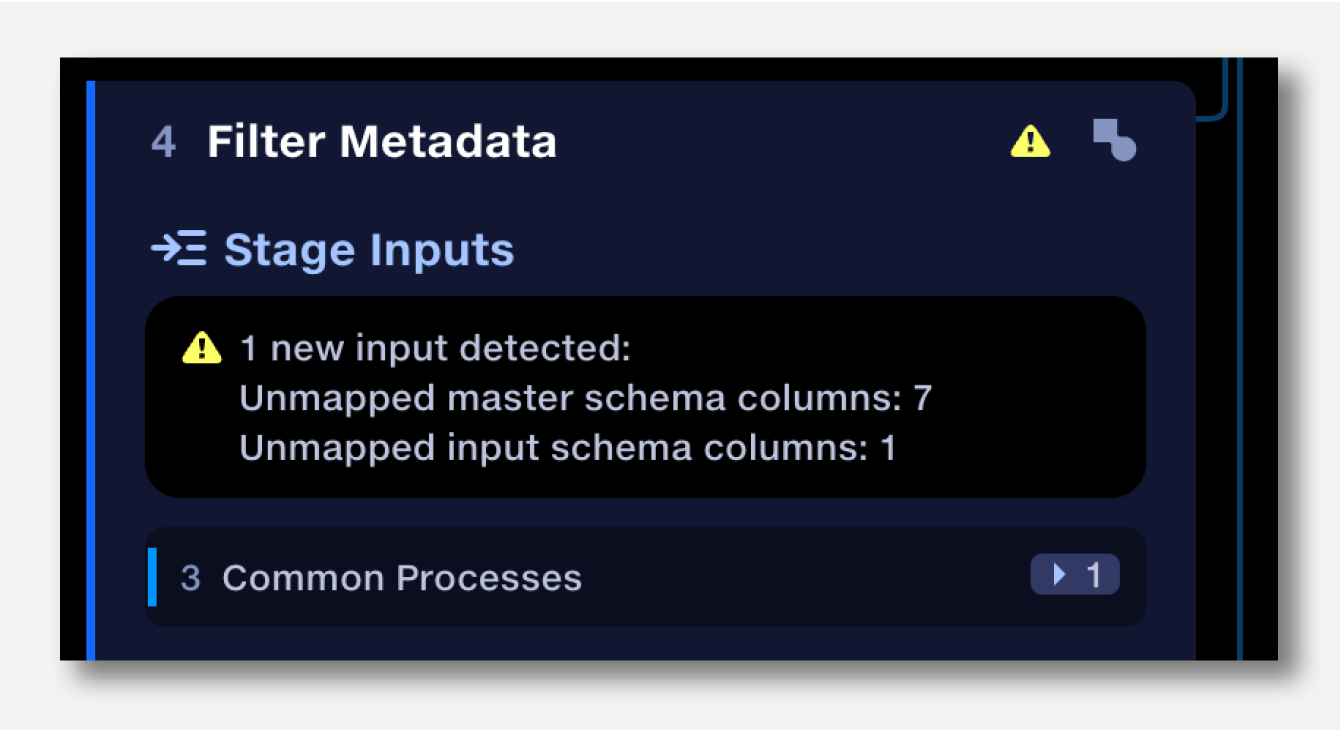
Example
For a given source:
|
Source schema
|
|---|
|
Client name
|
|
Ref. no.
|
|
City
|
|
State
|
|
Country
|
and the following mappings:
|
Mappings
|
||
|---|---|---|
|
Client name
|
maps to
|
Client
|
|
Country
|
maps to
|
Territory
|
|
Ref. no.
|
maps to
|
Ref. no.
|
Scenario 1
Adding another input with the same schema as the initial source will apply the same set of mappings to that new input.
Scenario 2
Adding another input with a different set of column names will apply the default mapping rules, matching column names ignoring capitalisation
For a new source schema:
|
New schema
|
|---|
|
client
|
|
ref
|
|
territory
|
will result in the mappings:
|
Mappings
|
||
|---|---|---|
|
client
|
maps to
|
Client
|
|
territory
|
maps to
|
Territory
|
Populating source fields
When a source file has no data for a master field, that field will be output as an empty column by default. This column can be populated with homogenous data if required. For example, if your master schema contains the field currency, yet your source data has no currency column, then the empty fields can be populated with a currency value.
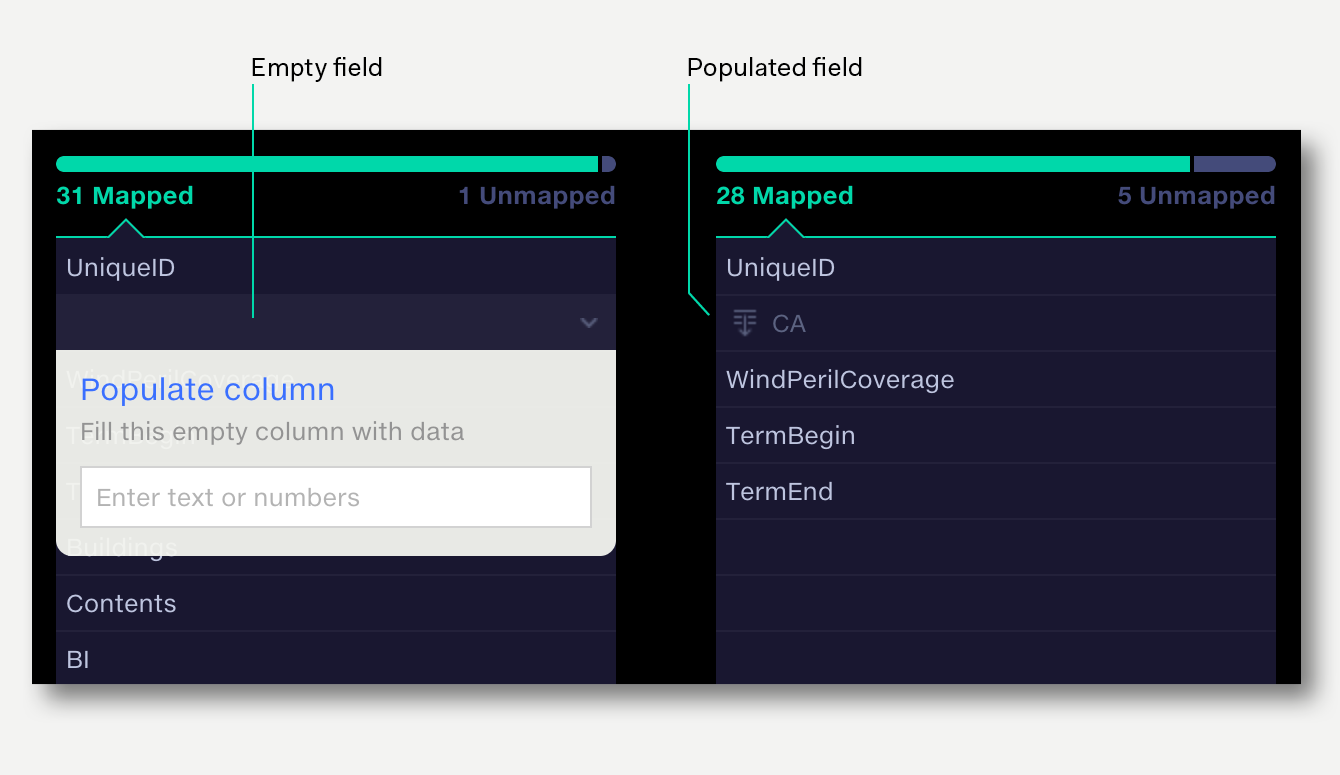
Using the populate function
To populate a source column:
- Click on an empty mapped item.
- Select populate.
- Enter text or numbers then hit return (↵).
- The data you have entered is shown in the field, alongside the populate symbol.
To remove populated data
- Click on an empty mapped item
- Select populate
- Delete the data from the the populate field then hit return (↵)
Populate all unmapped fields at once
Sometimes source datasets may not contain all the columns in your master schema. It’s often useful to populate these blank columns with a single value, such as ‘Unmapped’, so when the data is used in Analyse, these datapoints can be identified and filtered out.
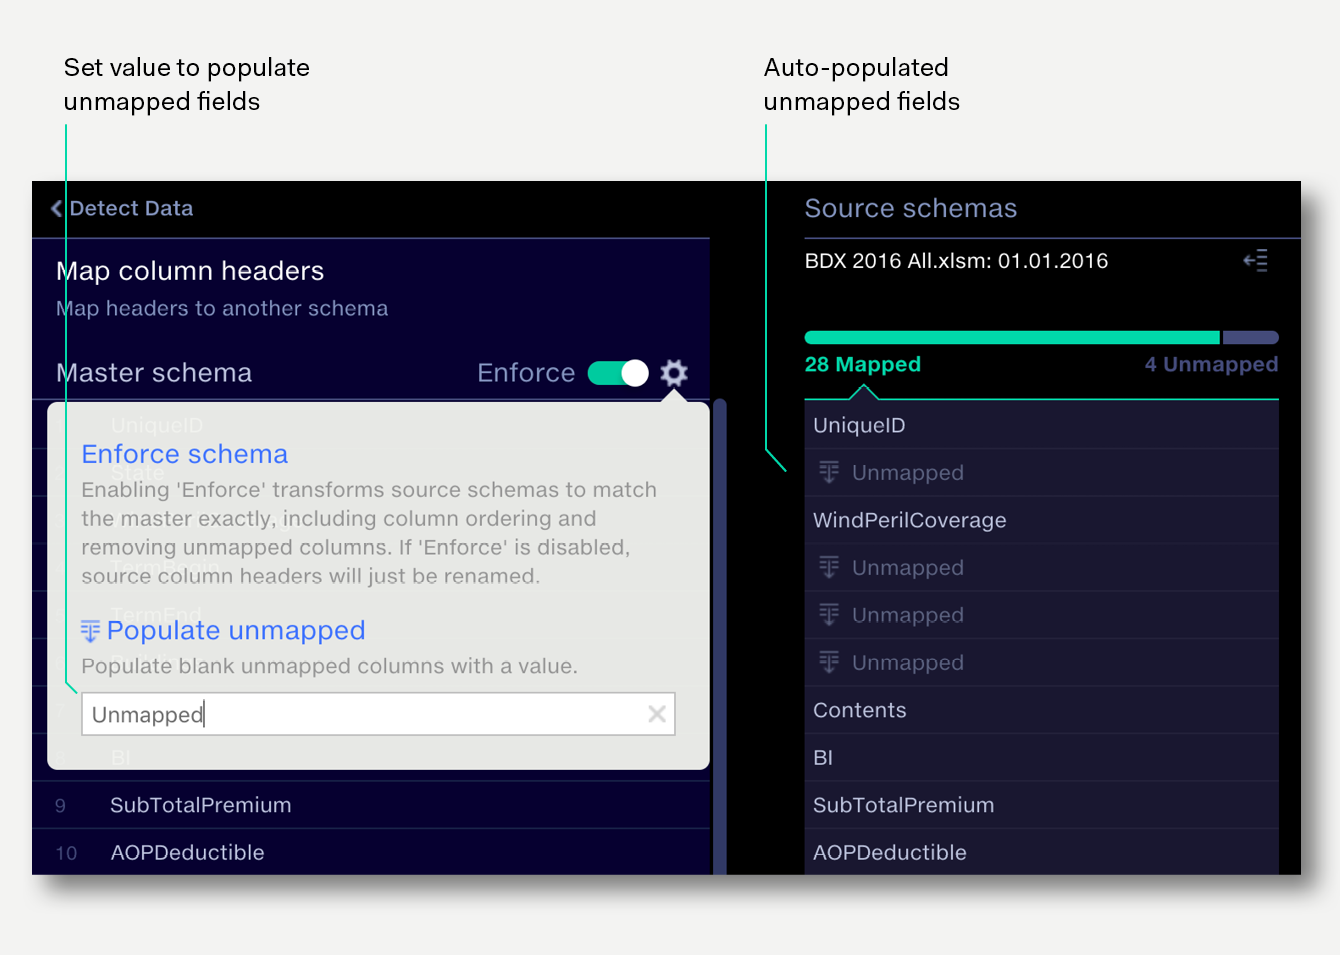
To populate all unmapped fields
- Click on the 'Populate' icon at the top of the Master Schema panel.
- Enter a value for ‘Populate unmapped’. The unmapped fields update live as you type.
Auto-populated unmapped fields can be overridden with an individual populated value. If the value for the auto-populated field changes, the overridden value is retained.
Automap
The Automap function automates the column header mapping process by applying all suggested mappings above a user-specified strength threshold.
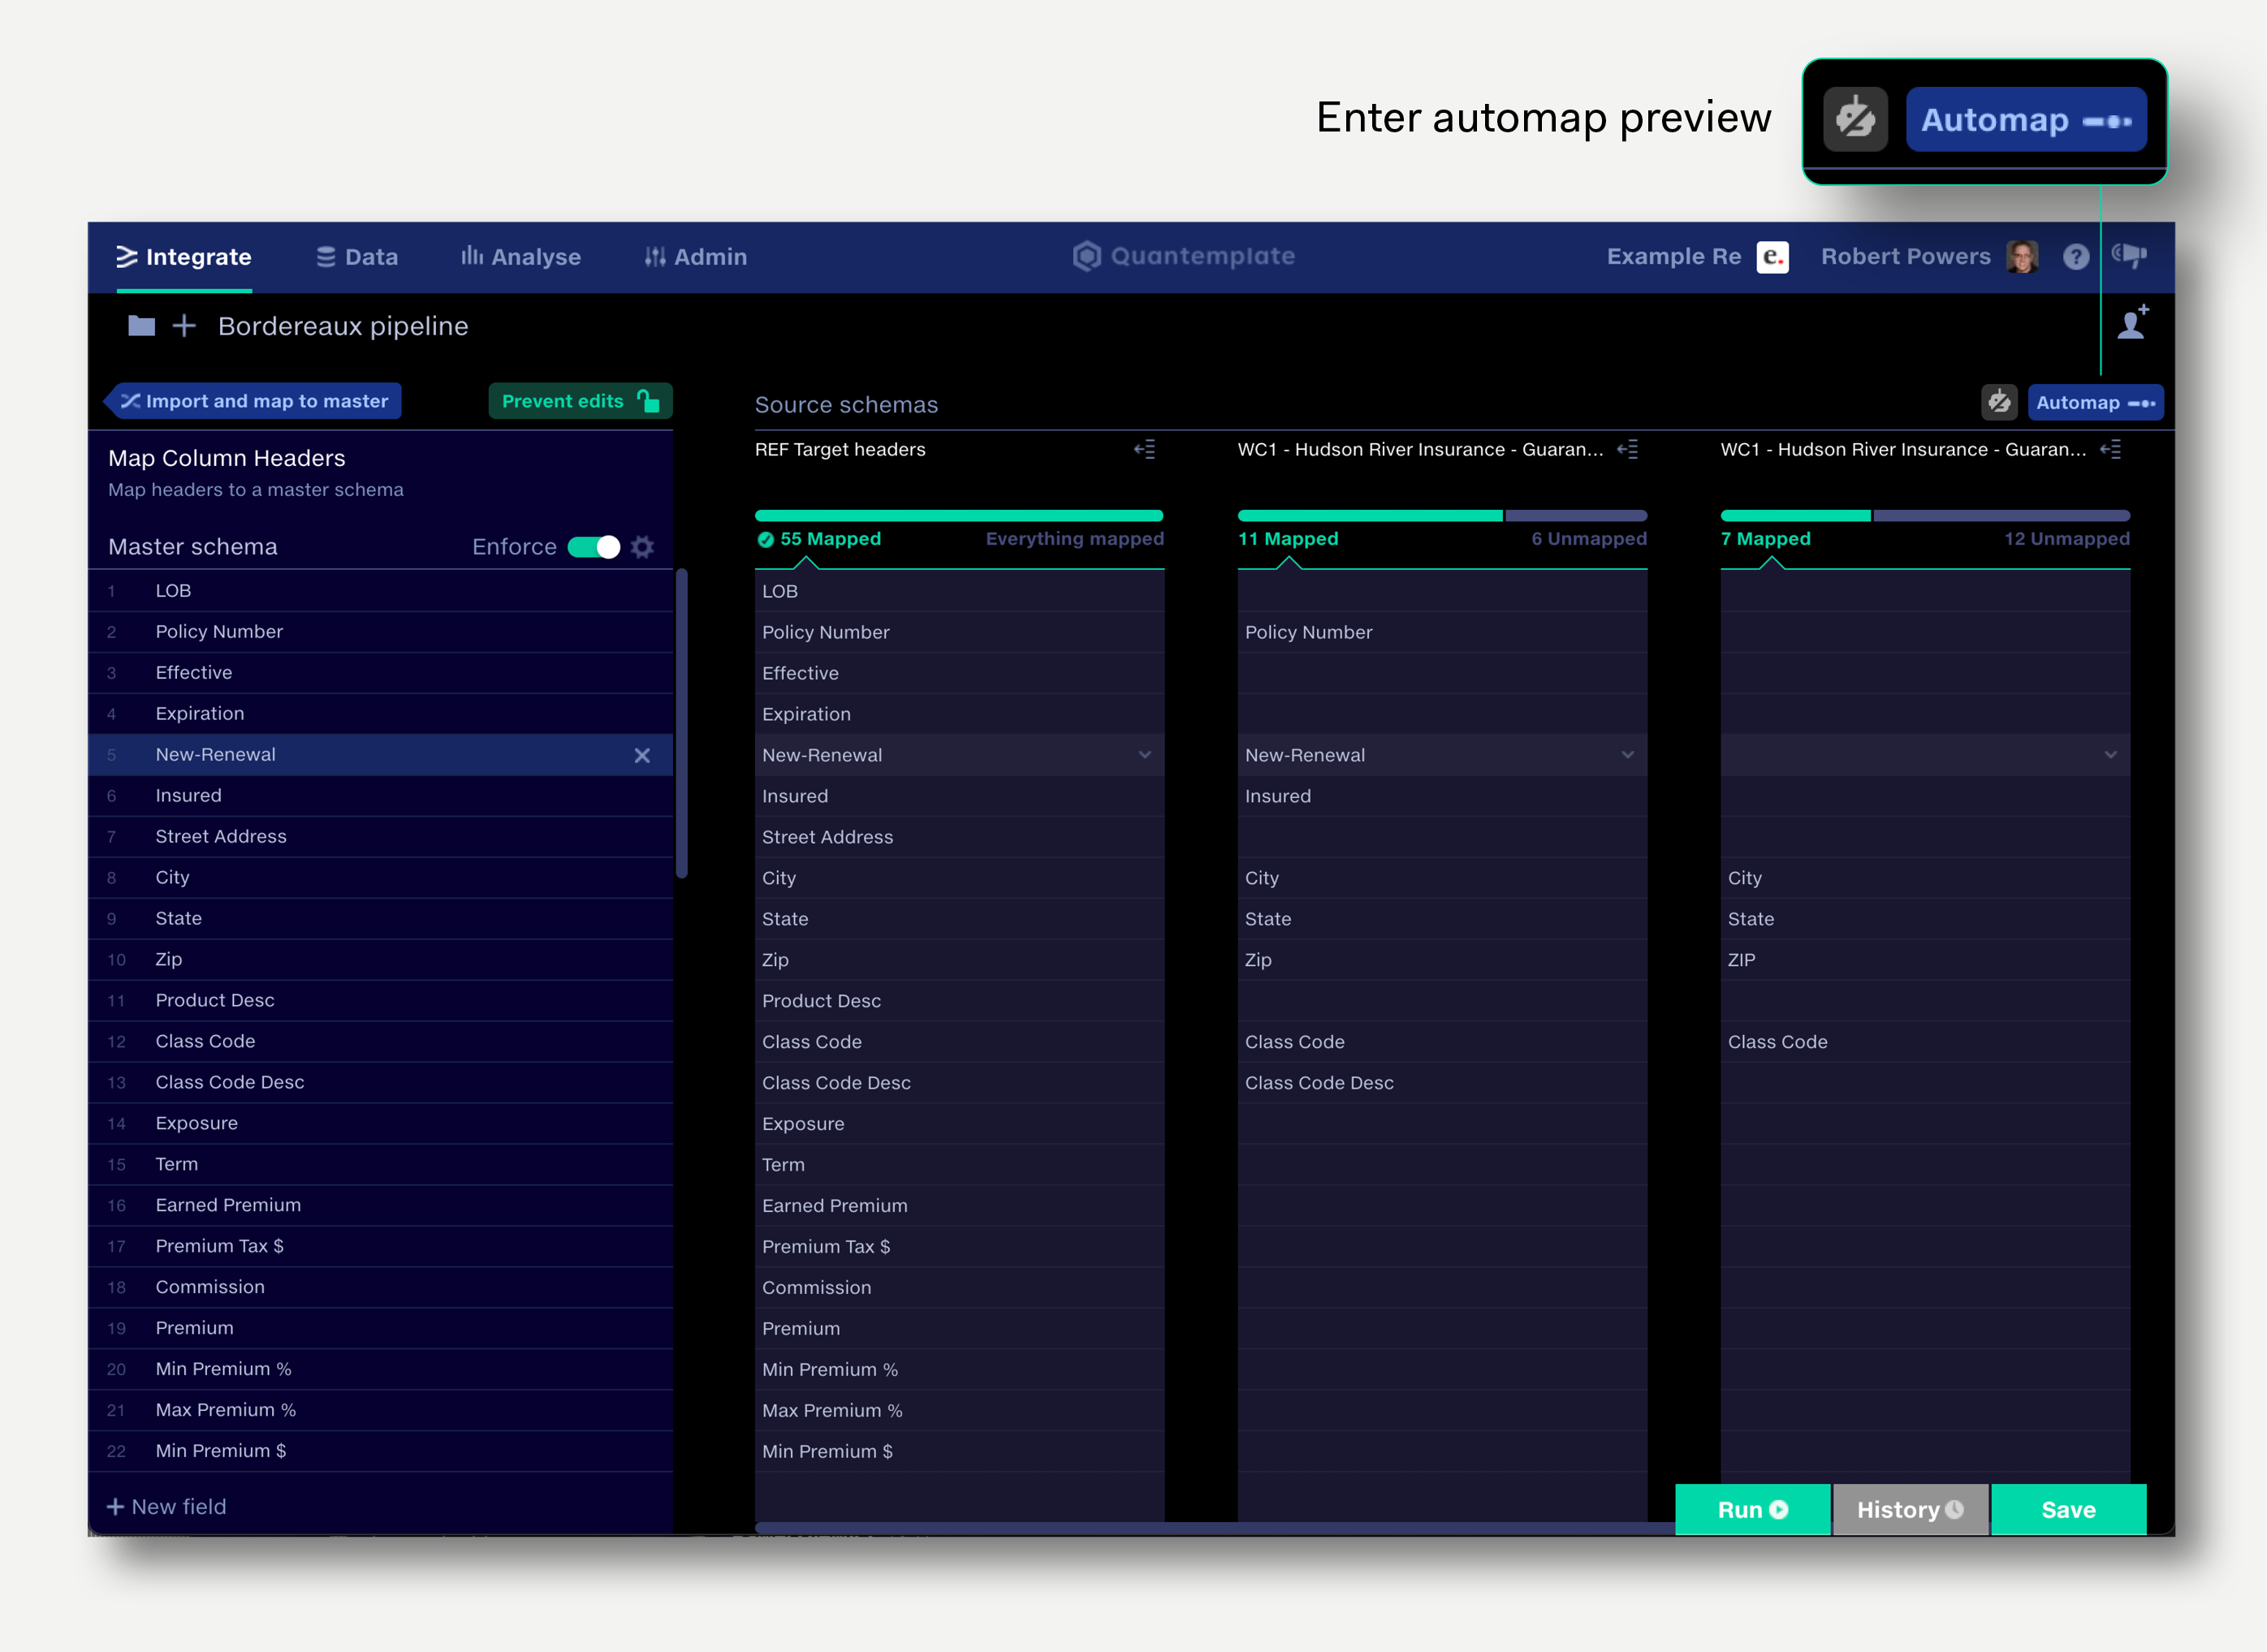
The Automap preview mode shows the effect of adjusting the strength threshold on the applied mappings.
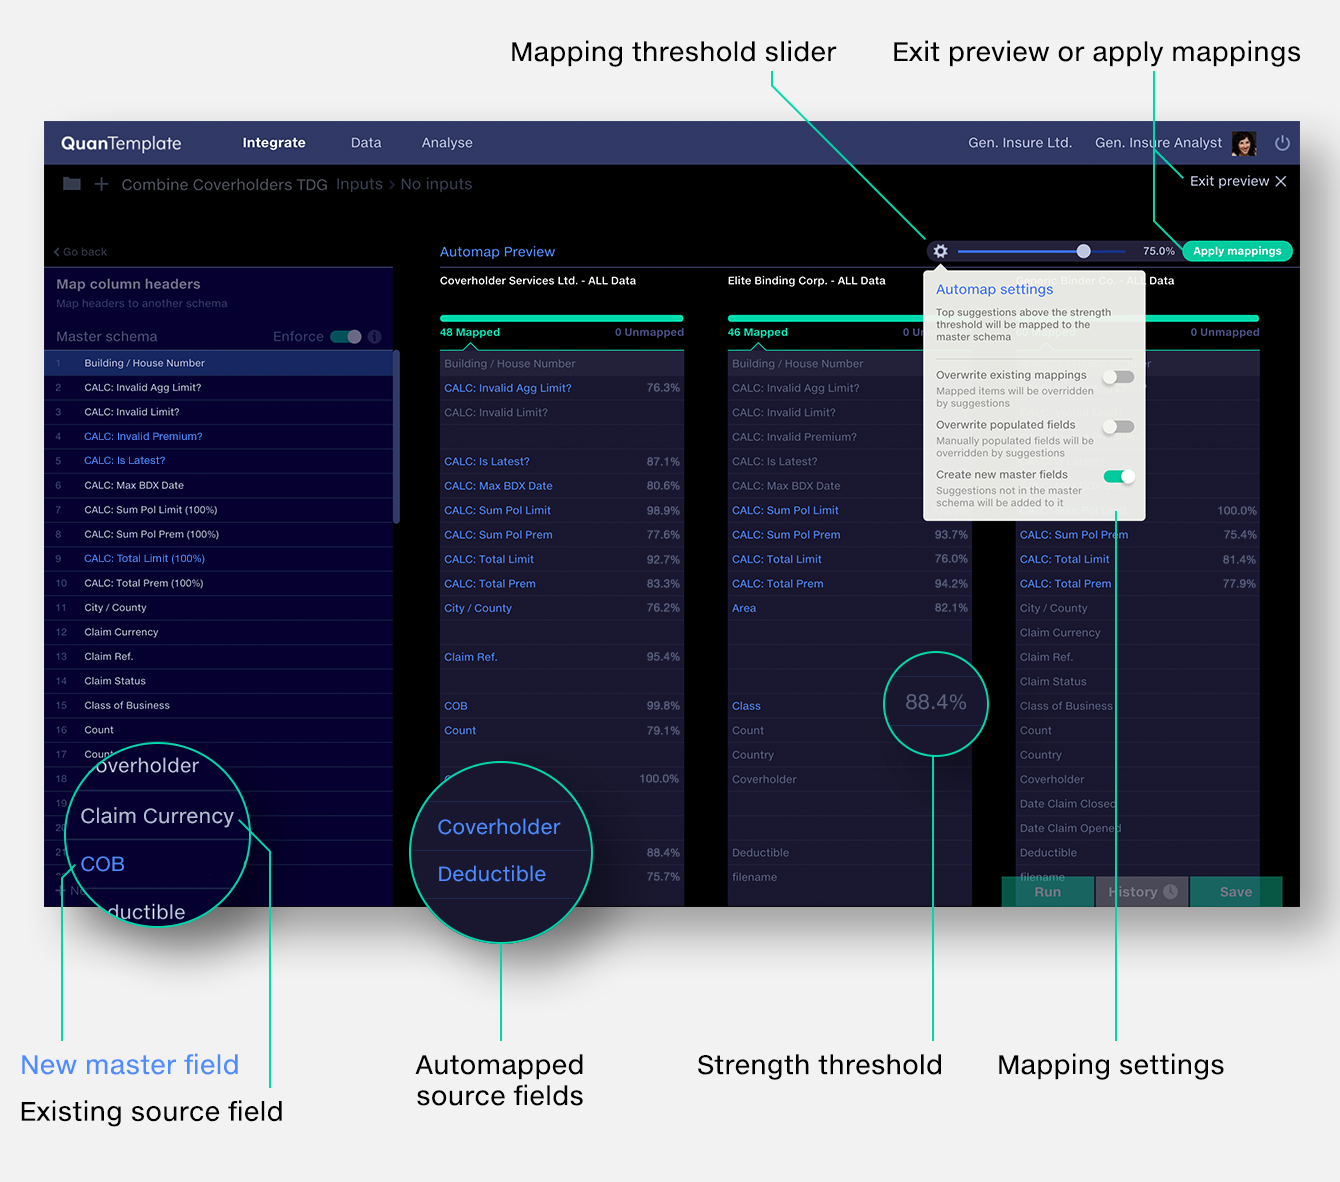
To Automap:
- Click the Automap button to reveal the automap preview.
- Select the desired automap settings via the settings cog.
- Drag the slider to the desired threshold.
- Click the ‘Apply mappings’ button to apply the mappings
and leave the preview, or click
‘Exit preview’ to disregard the mappings.
Note that for any given schema mapping suggestions and strength ratings may change over time as the ML-powered decision-making model learns from your mapping choices.
Automap settings
Overwrite existing mappings
Mapped items will be overridden by suggestions. This is a ‘destructive’ mapping option since any mappings you have made previously will be overwritten. Off by default.
Overwrite populated fields
Fields which have been populated on a per-column basis will be overridden by suggestions. This is a ‘destructive’ mapping option since any per-column populated fields you have made previously will be overwritten. Off by default.
Note that fields which have been populated at a master schema level using the populate all function will always be overwritten by Automap.
Create new master fields
Suggested mappings that are not in the master schema will be added to it. Note that the field that will be added to the master schema will be a mapping suggestion based on other mappings made within your organisation, not necessarily the exact field name in the source schema. The suggestion must also exceed the automap threshold for it to be mapped in. If you wish to add in additional columns with their names unchanged, consider enabling the rename only option.
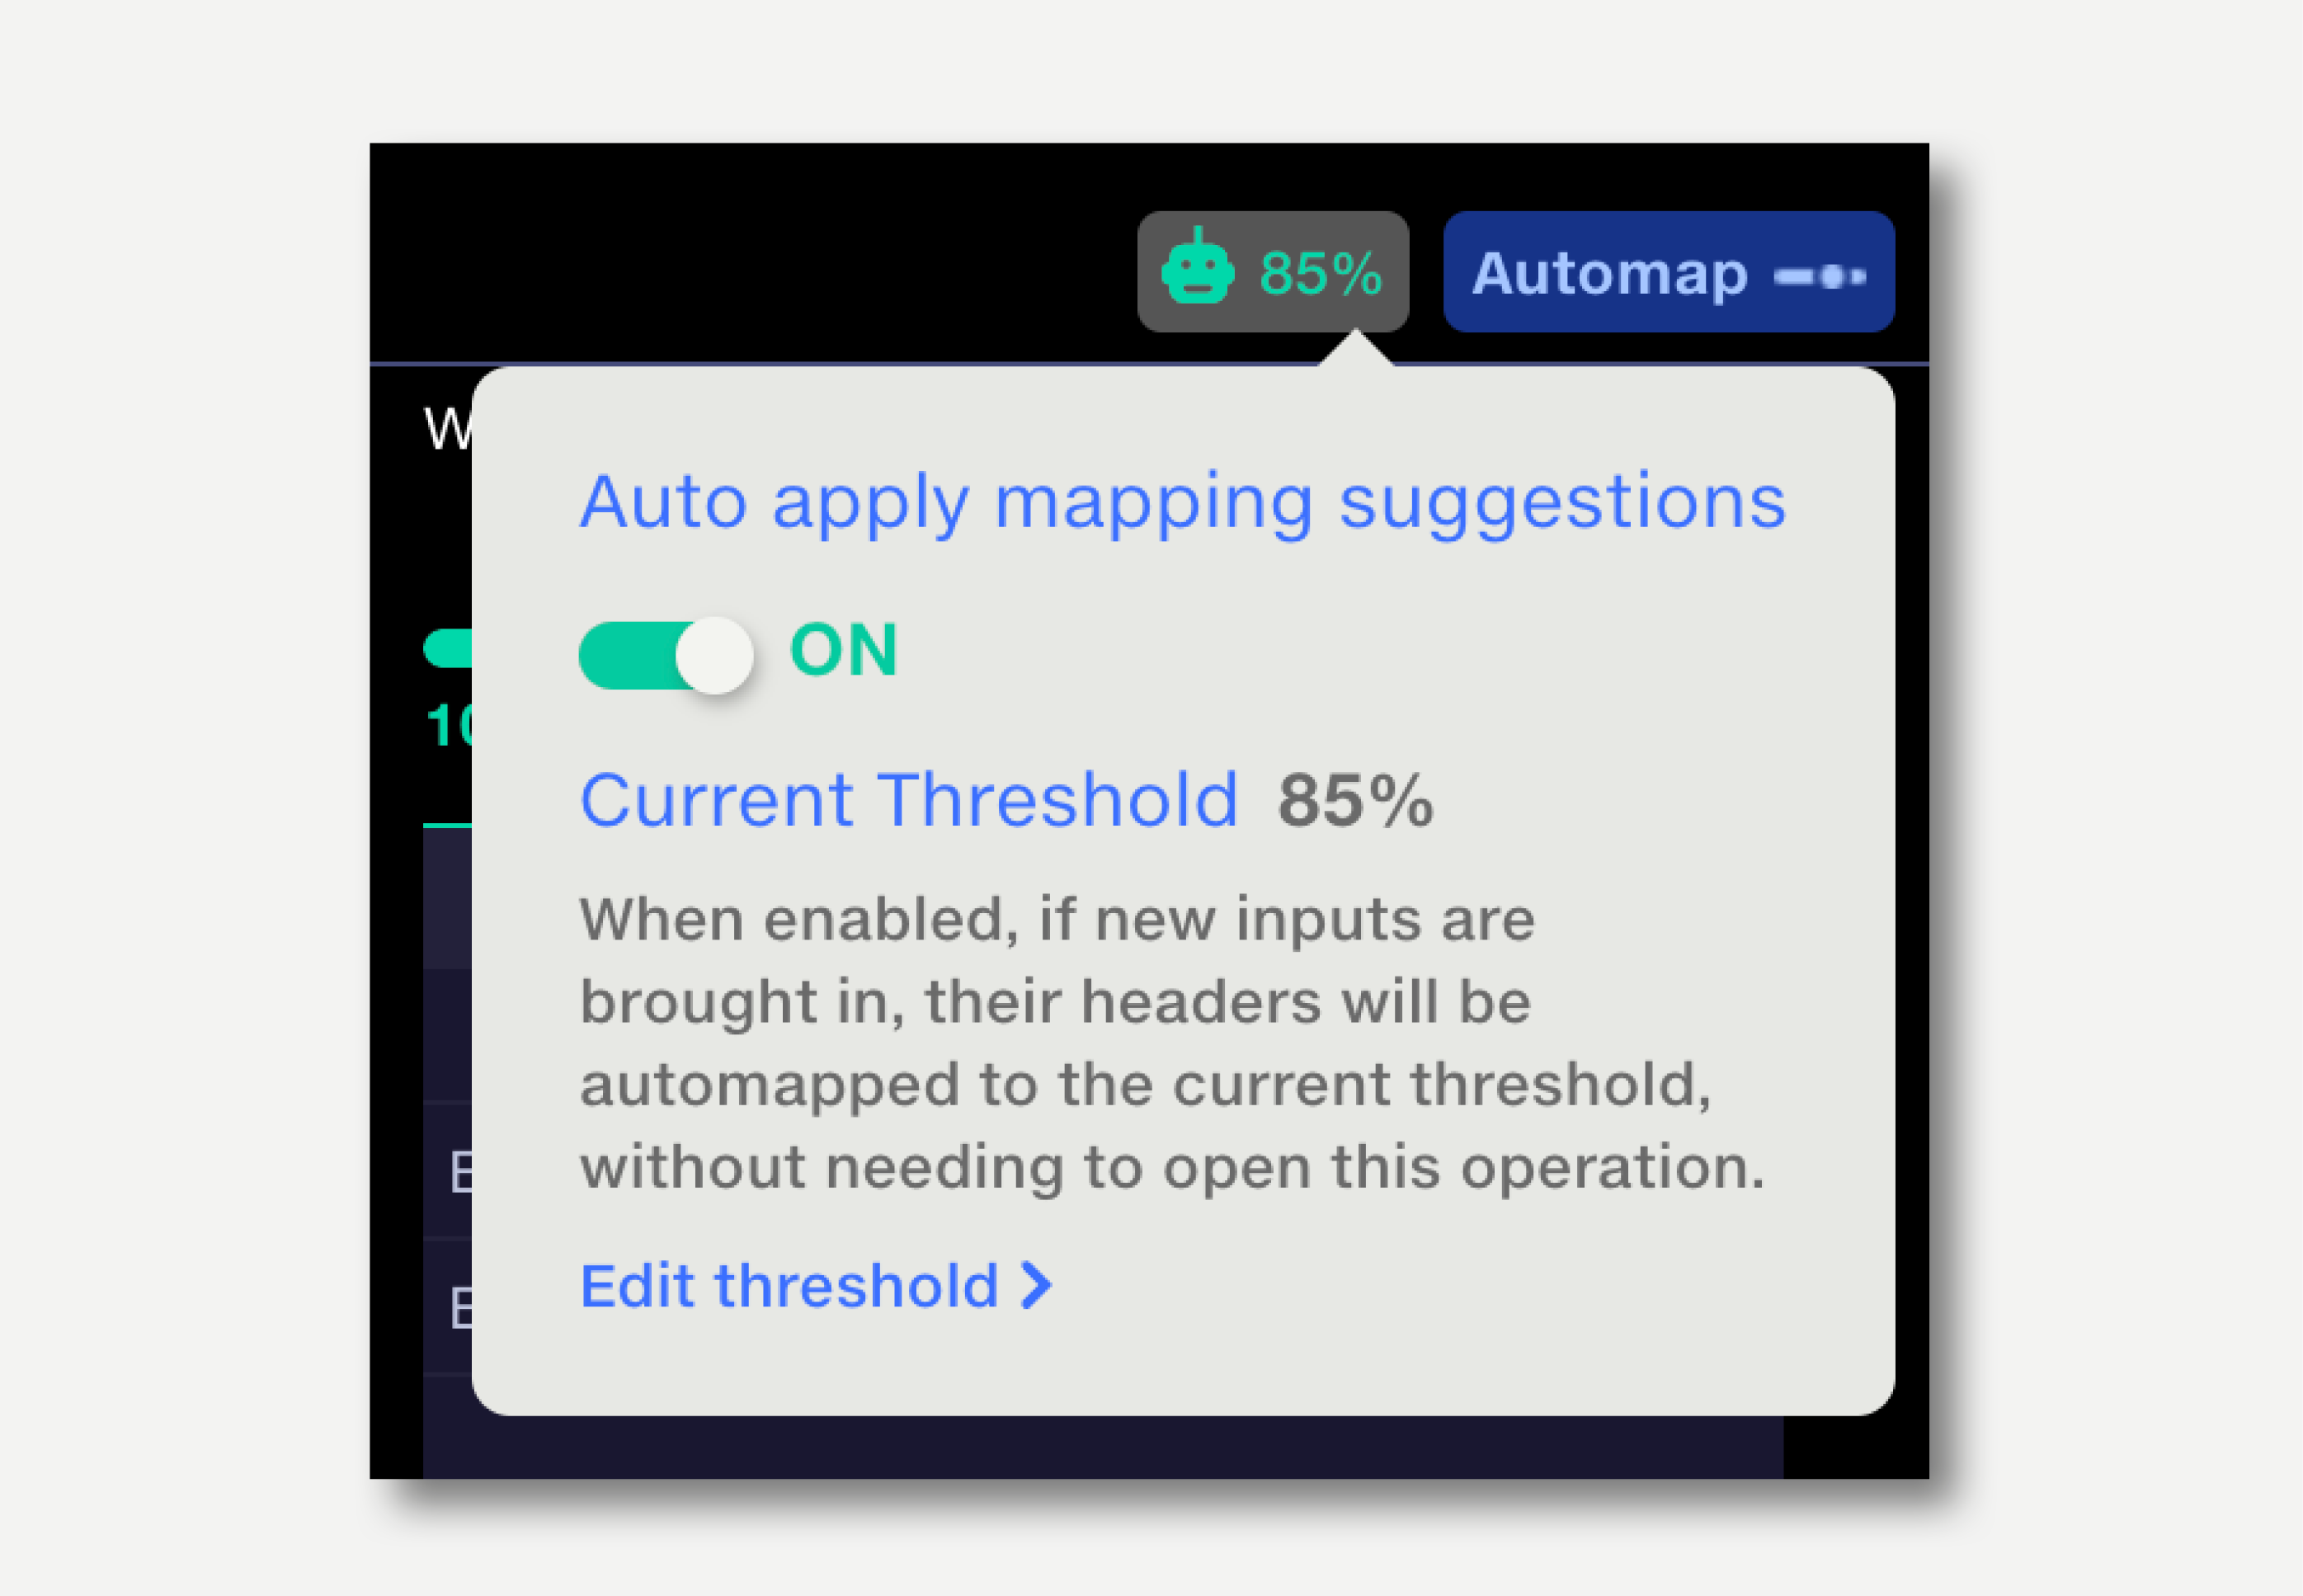
Auto apply mapping suggestions
Ordinarily, if an input file comes in with an unrecognised schema the user will need to map the file in again, assisted by the Automap feature which remembers previous mappings.
If the Automap feature is set to auto apply, there is no need for a user to open the Map Column Headers operation to map in the new file: Automap will map the all headers to the master schema that it finds a match for, above the strength threshold set in the operation. If the pipeline run has been triggered automatically (by a dataset update event, for example), there is no need to open the pipeline.
To enable auto apply, click the robot button next to the Automap button and set the toggle to ON.