

Data
Data repo
The Data repo is the storage area for clean datasets. This includes reference data to be used in pipelines and cleansed pipeline outputs.
Datasets in the Data repo can also be used to chain pipelines together.
Dataset requirements
Datasets with a single row of headers can be uploaded directly to the Data repo to create a reference dataset for use in pipelines, for example a target header schema to map to. The upload process will ignore any blank rows above or below the data, or blank columns either side of the data. The first line of data will be interpreted as column headers.
Read more about uploading data to the Data repo.
Cleansed outputs from pipelines can also be exported to the Data repo for onward sharing via API, sharing within Quantemplate, or reporting in Analyse.
Import and export via API
Quantemplate’s APIs allow you to import to a dataset (overwrite it) and export a dataset whenever it is updated.
This can be combined with Automation features to:
- Trigger a pipeline run whenever the API connection updates a dataset in Quantemplate
- Automatically export a dataset whenever it is updated by a pipeline
Managing datasets
Quantemplate's newsfeed-style repos provides a live view of your dataset activity across your environment. Repos help you monitor dataset updates to keep track of the automated flow of data.
Metadata bar
The metadata bar below the dataset name displays information about how the dataset is used, updated and connected. Click on each item to reveal more details.
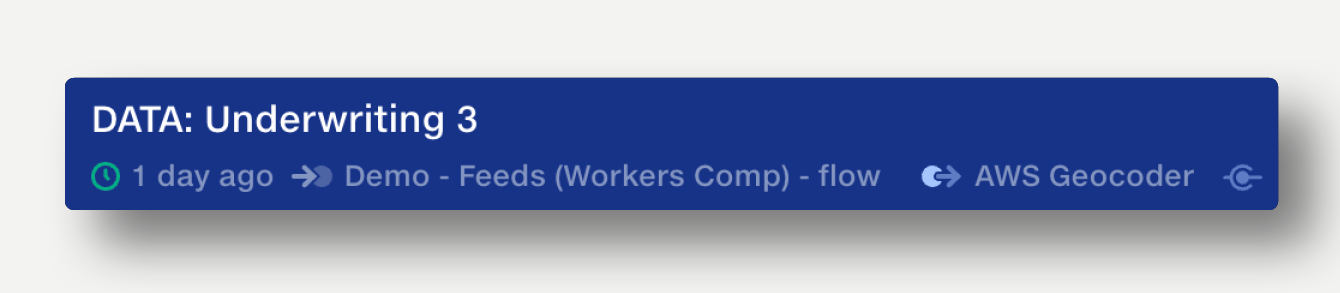
Last update
See if a dataset was updated, 'Just now', '1 minute ago' or even '1 year ago'. The clock icon changes tone depending on the recency of the last update, helping spot recent activity at-a-glance.
Last updated by
The metadata bar lists the last user or pipeline that updated the dataset. Click on the name to reveal more information or view the pipeline in a new tab.
API and robot
If the dataset has been shared with the API or Robot users, the API or Robot icon is displayed in the metadata bar.
Sort and search datasets
Datasets are sorted by 'Last update' by default. This updates live, keeping you up to date with the status of your partner data sharing.
Datasets can be sorted by dataset name, status, last updated date and last updated by user. Click the arrow button to reverse the sort direction. Your sorting choice will be remembered.
Click in the search field to search datasets by name.
Dataset information
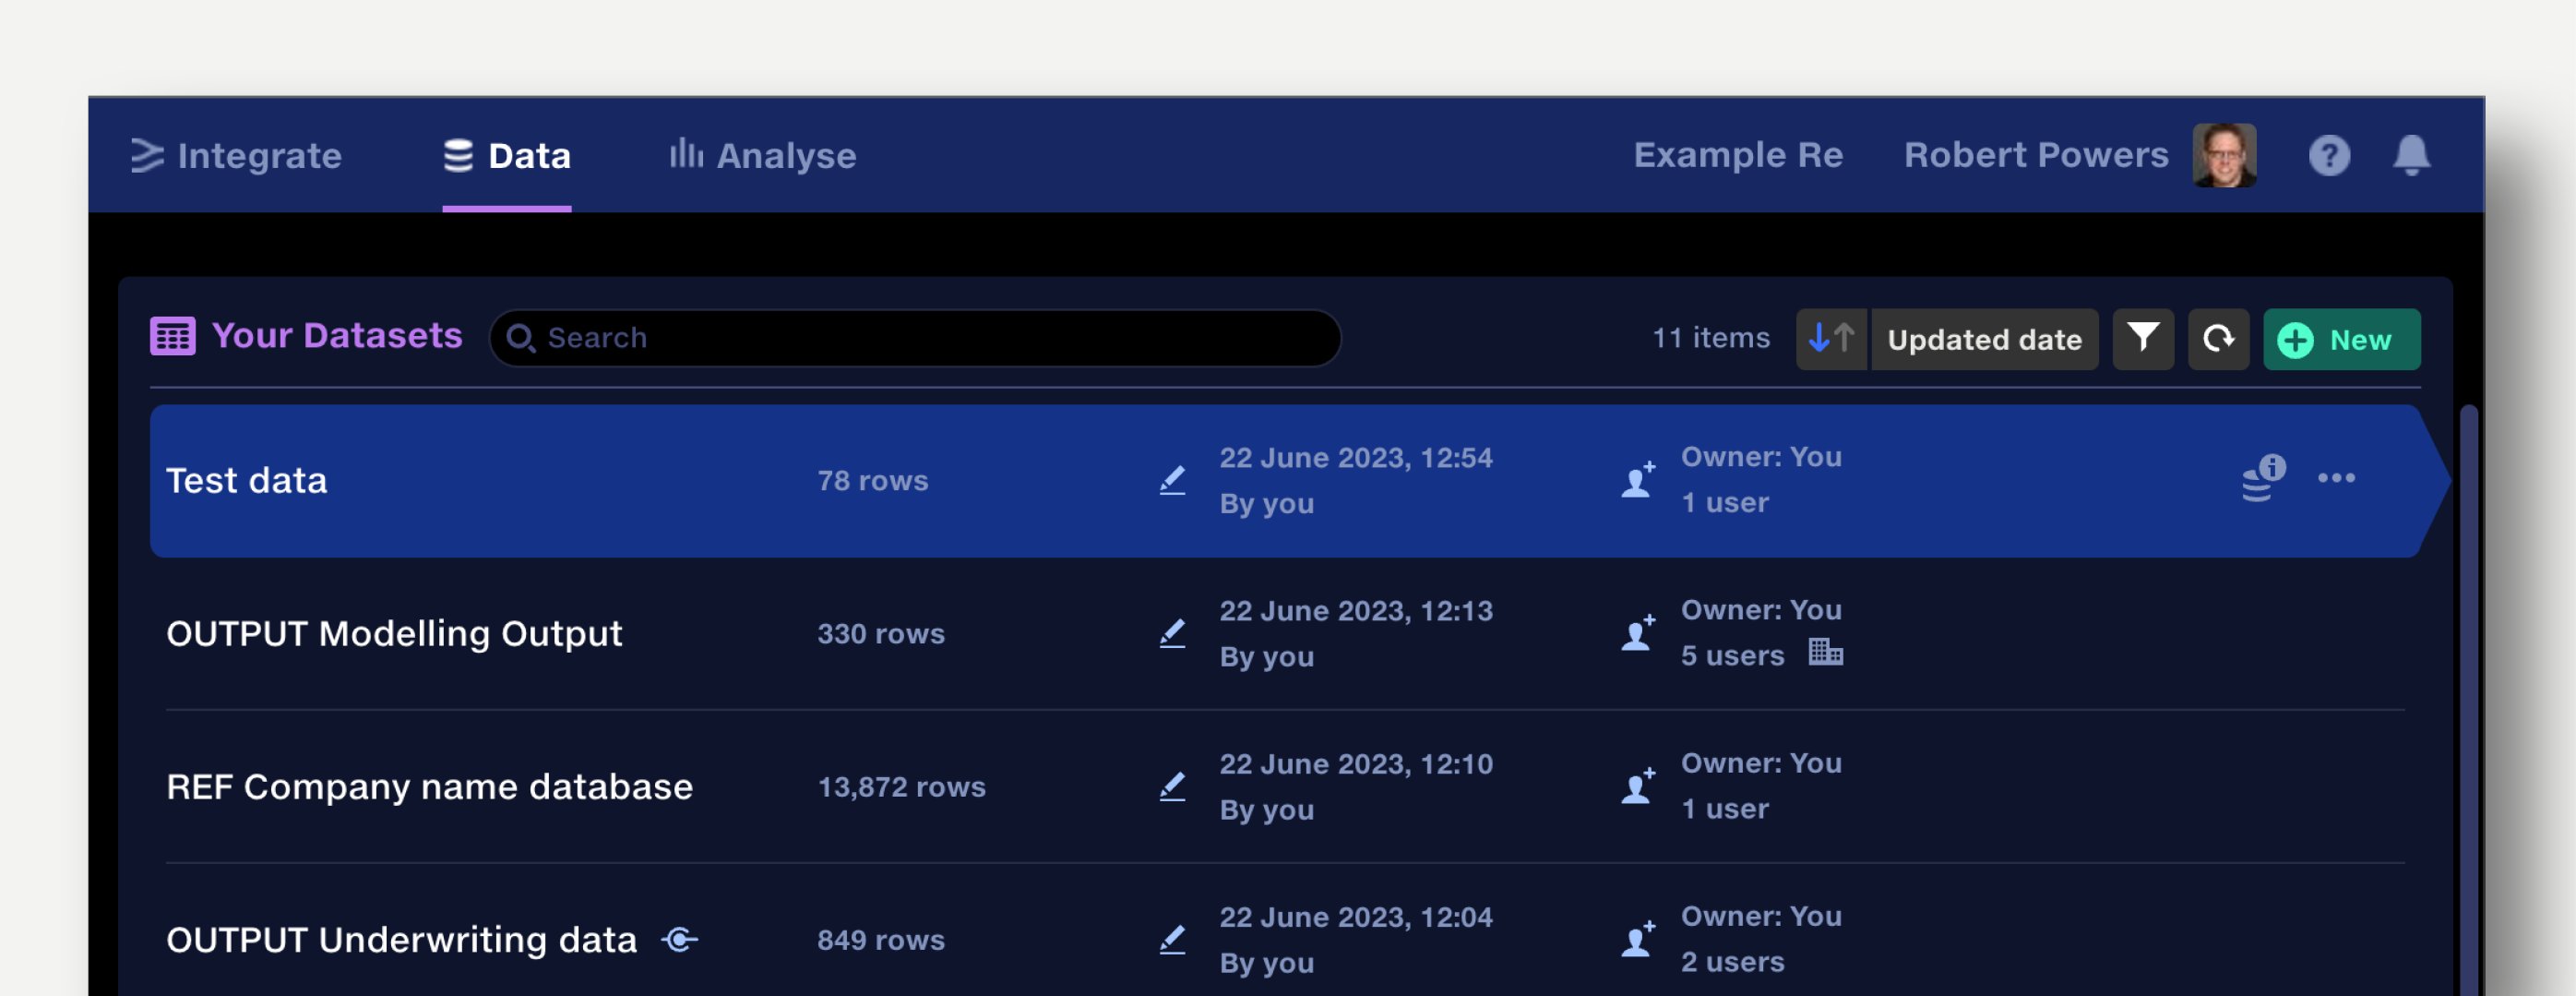
The repo view also shows:
- Dataset name
- Tags applied to a dataset
- A lock icon if the dataset is Read Only
- Row count
- Last updated date
- Last updated by
- Owner
-
Number of users with access. Click to see details of users and manage access.
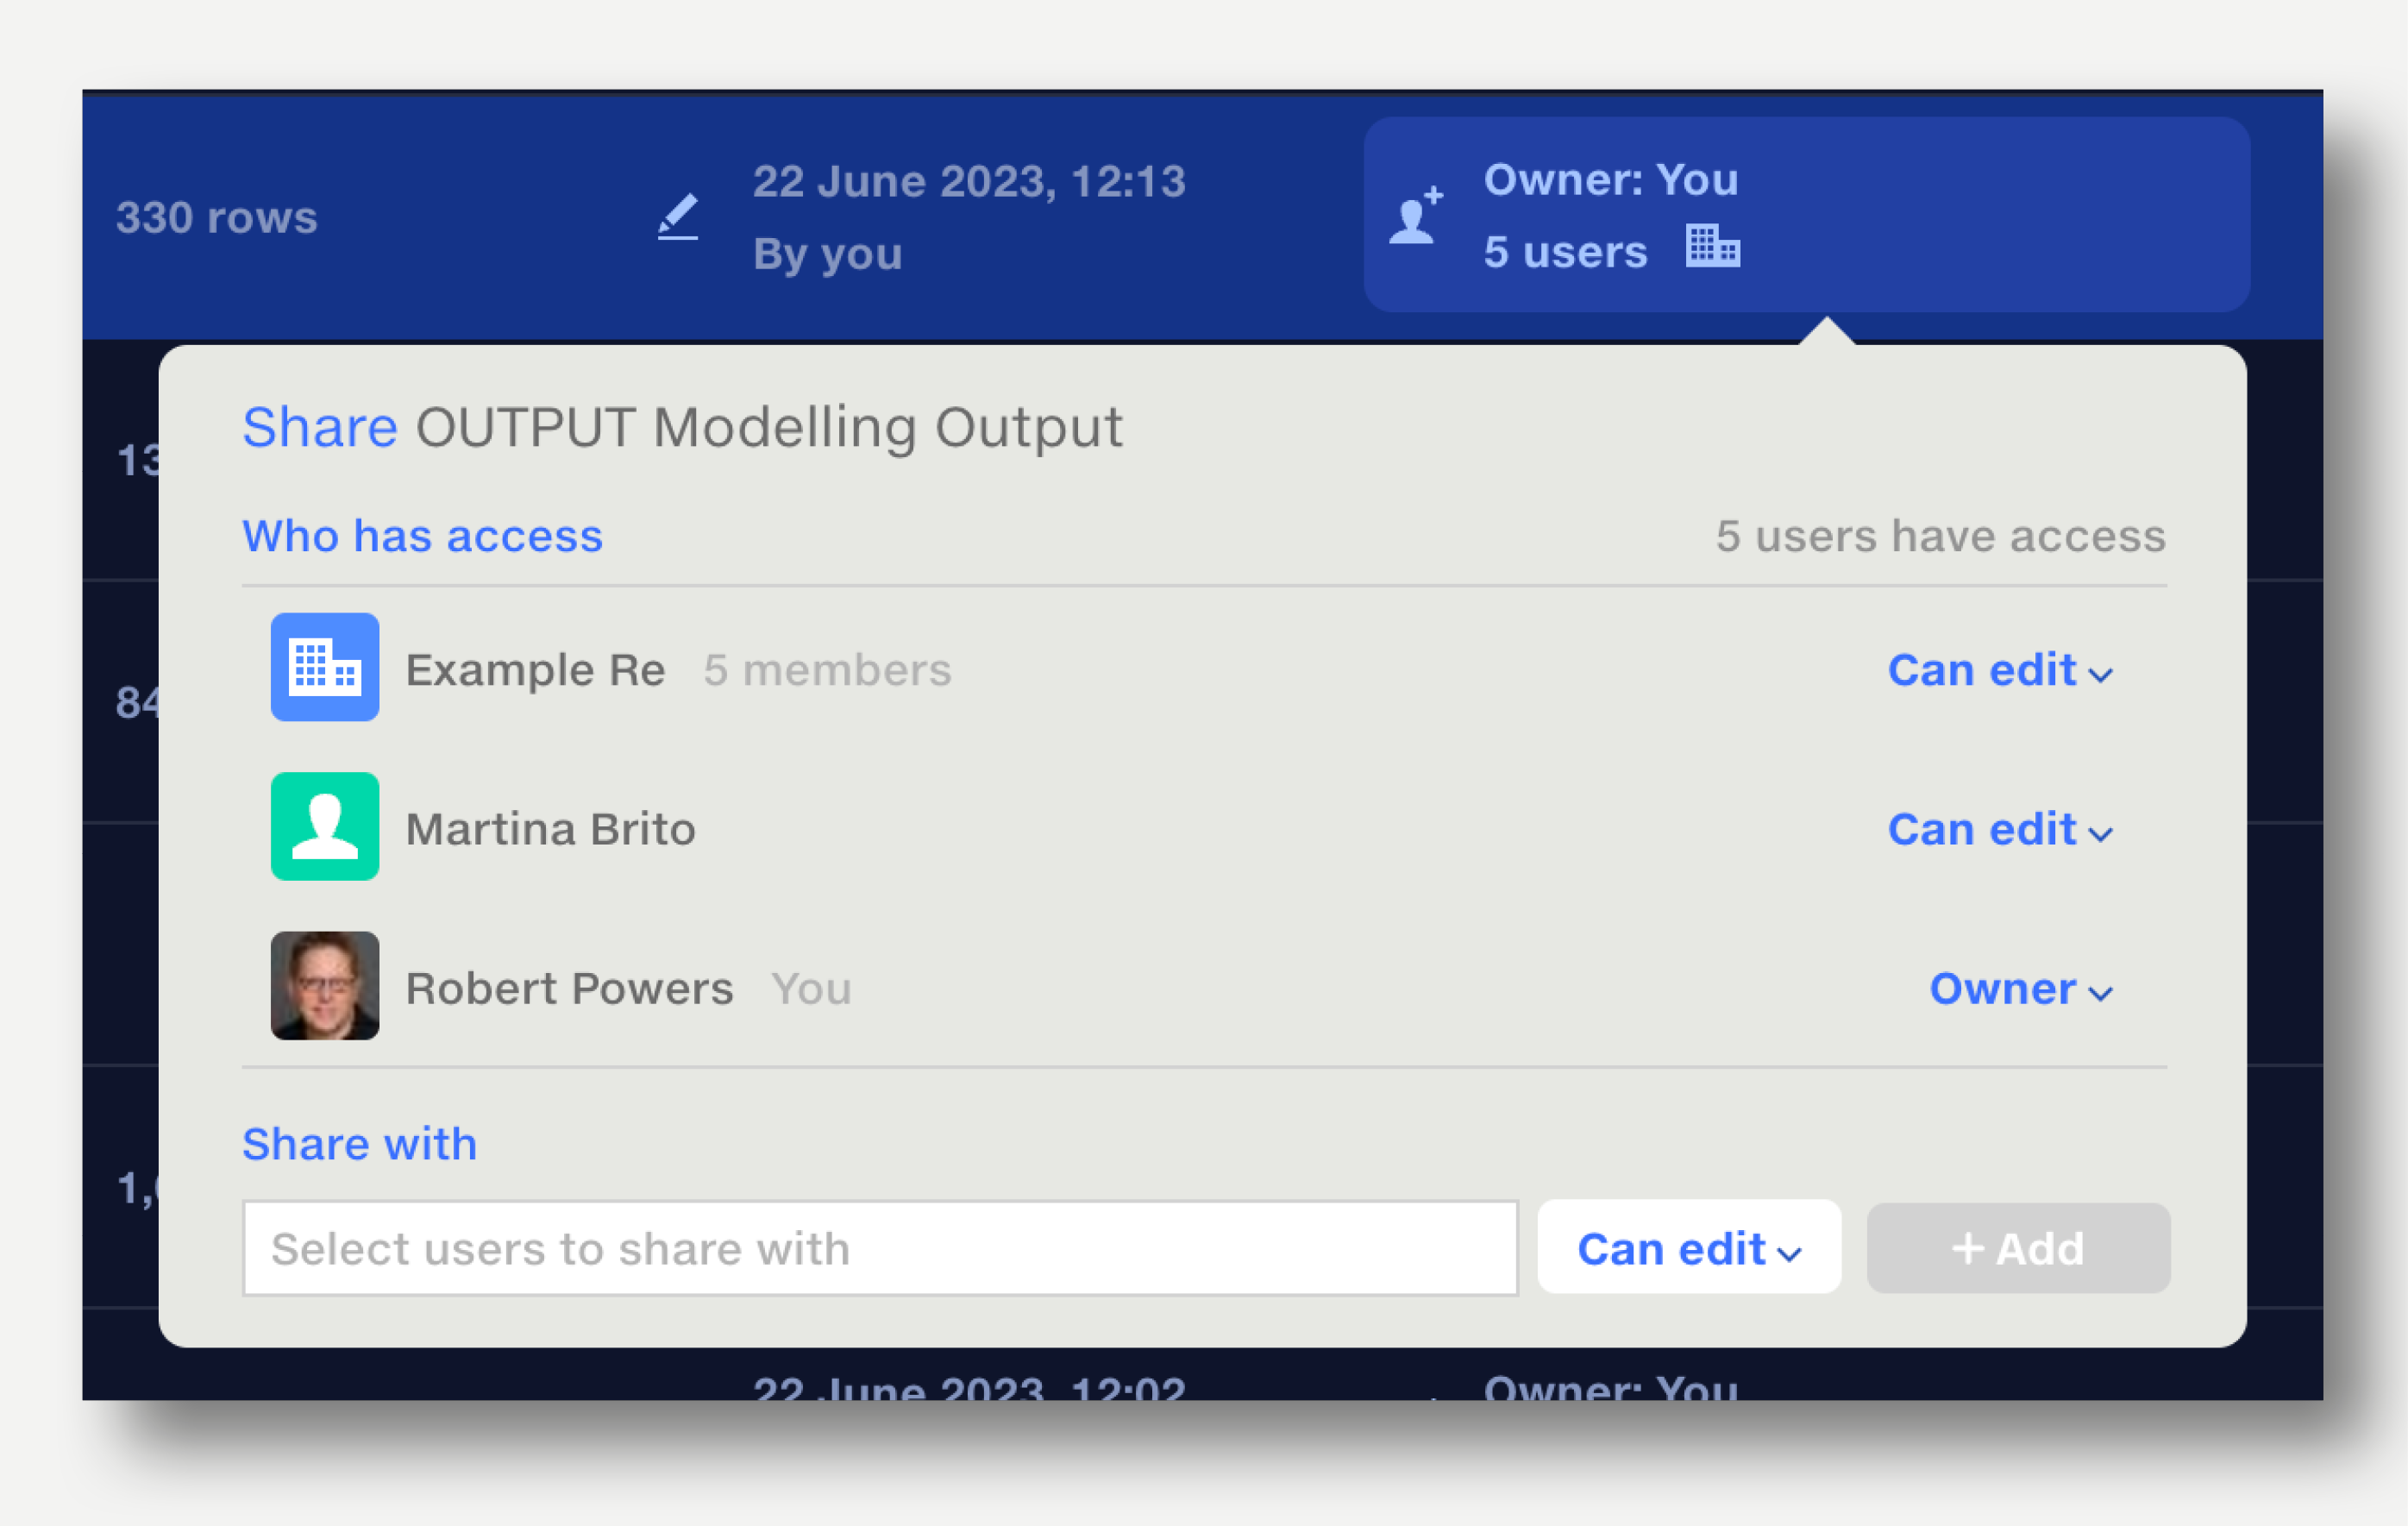
- Items shared with the whole organisation are indicated by the office-building icon
- Items shared with the API user are indicated by the API-connection icon
-
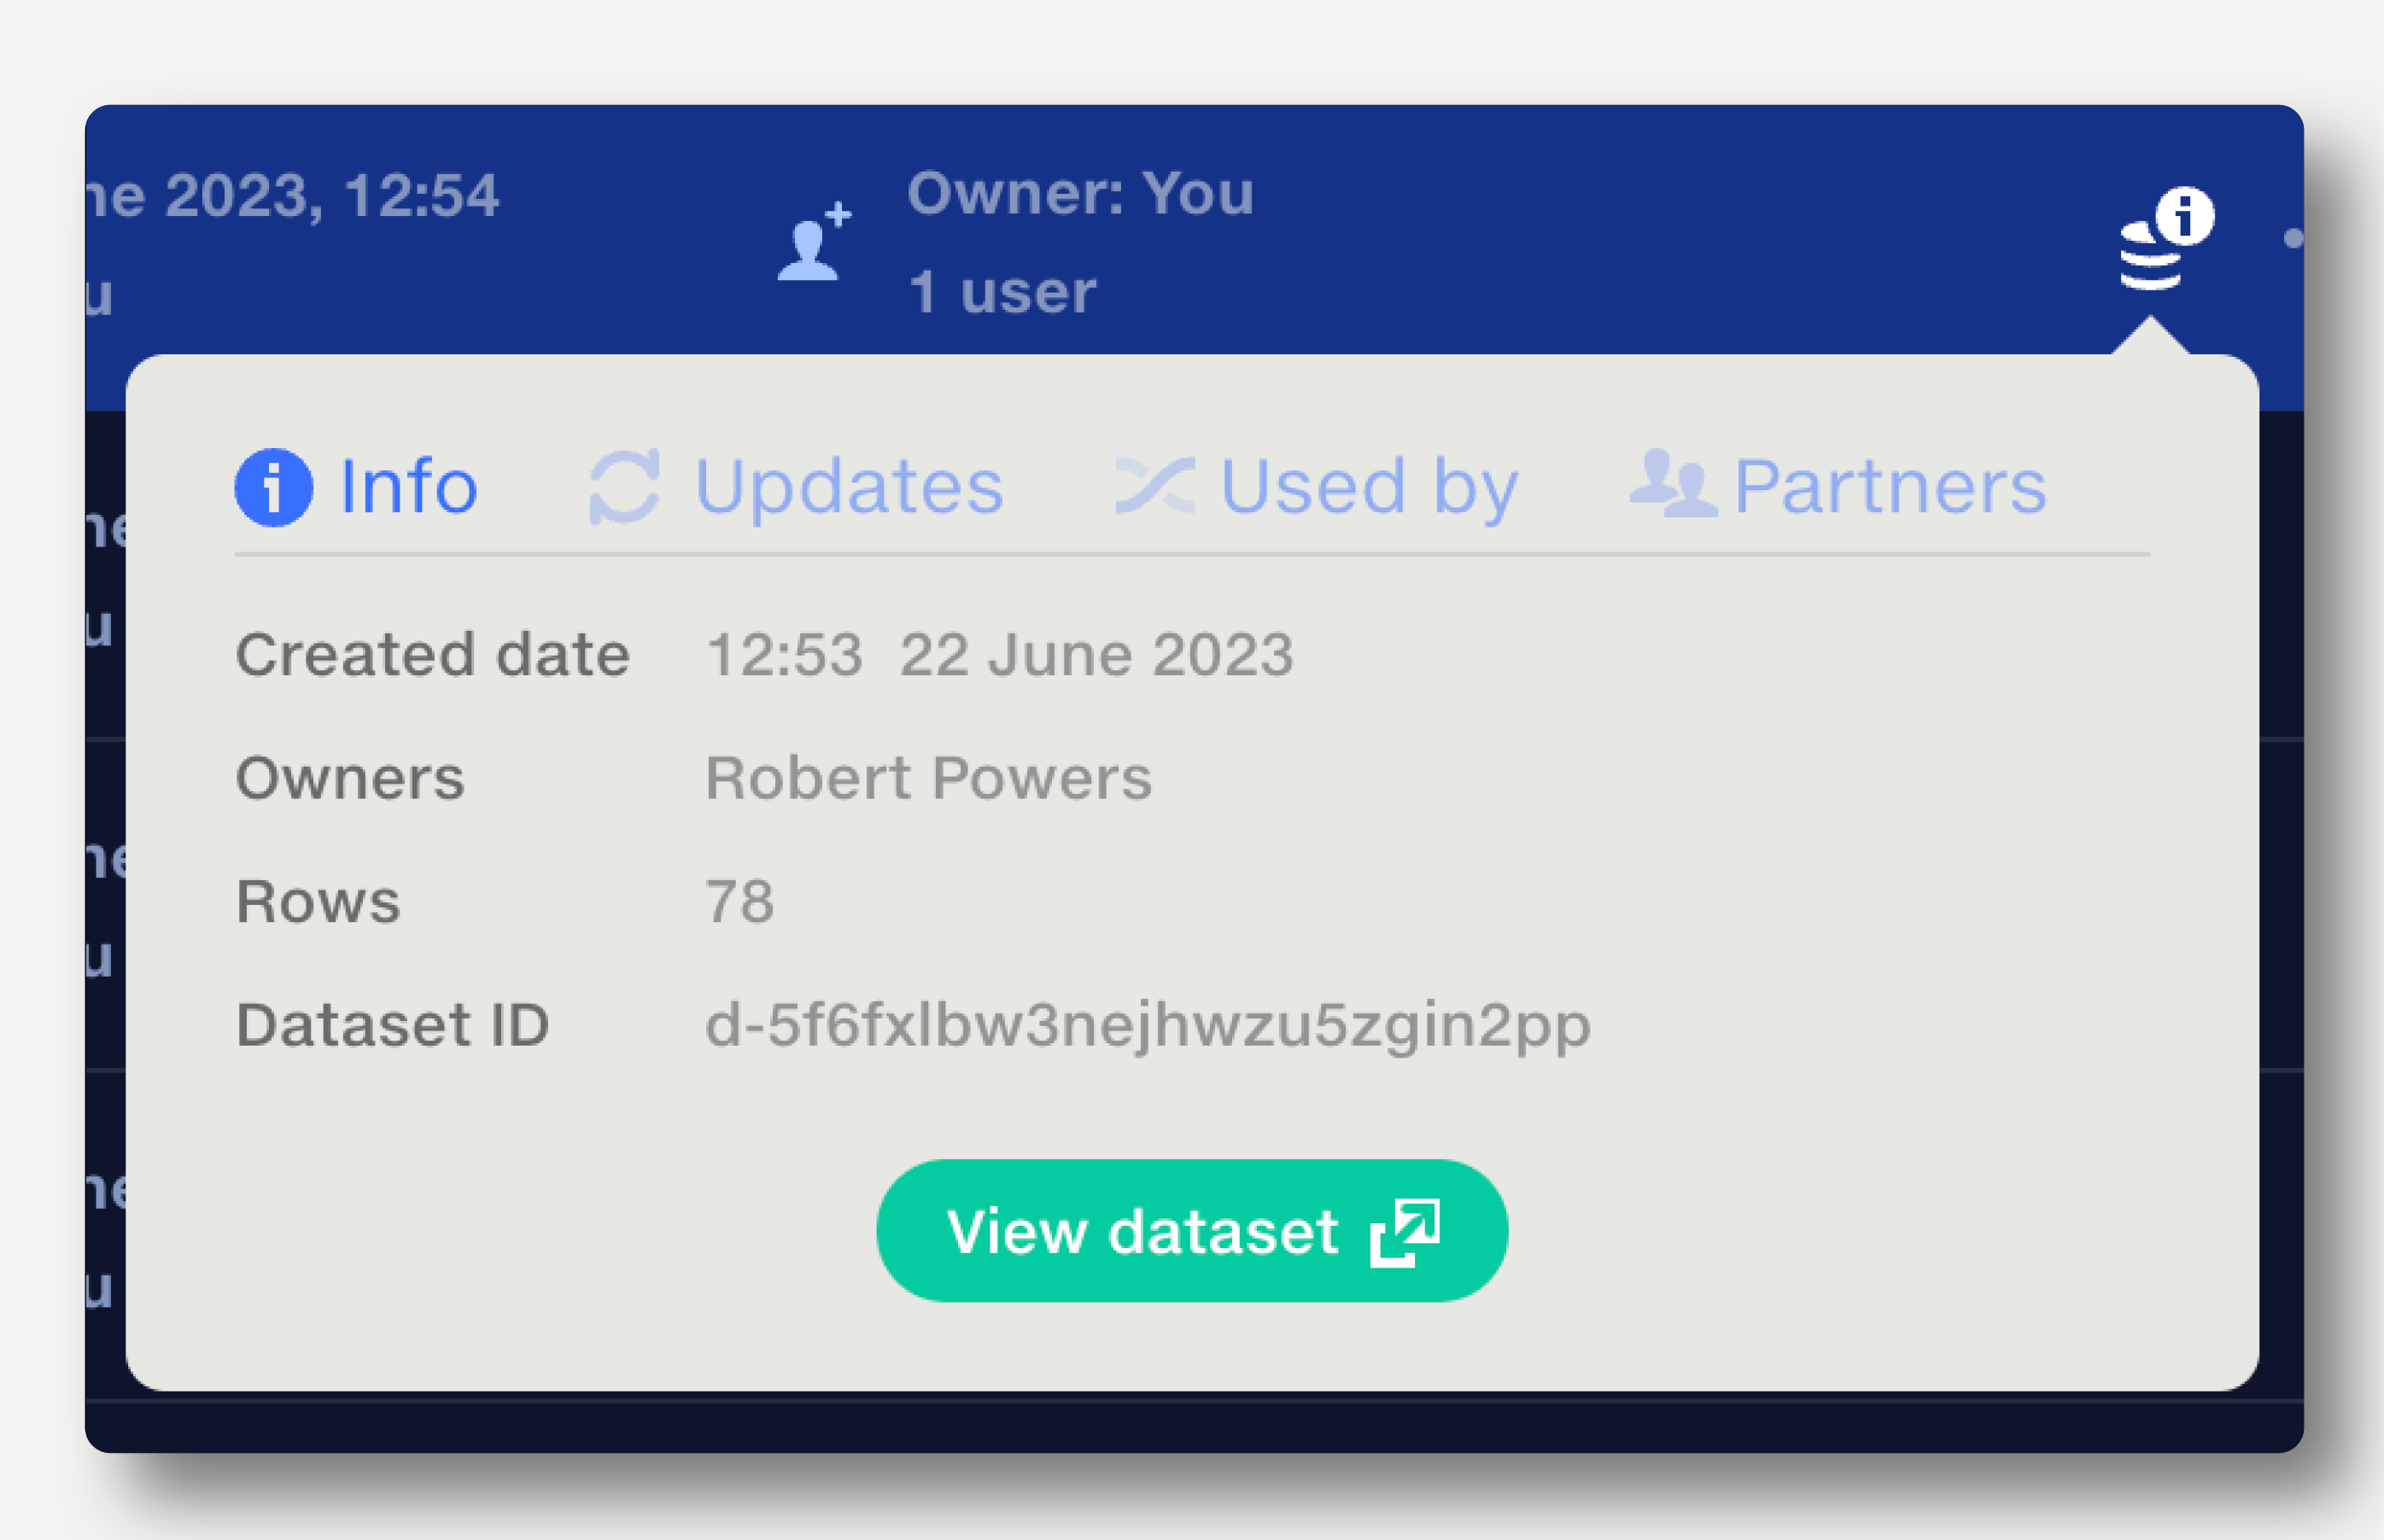
See the Dataset information popup for details on how a dataset was created, used, and shared externally.
Manage documents with tags
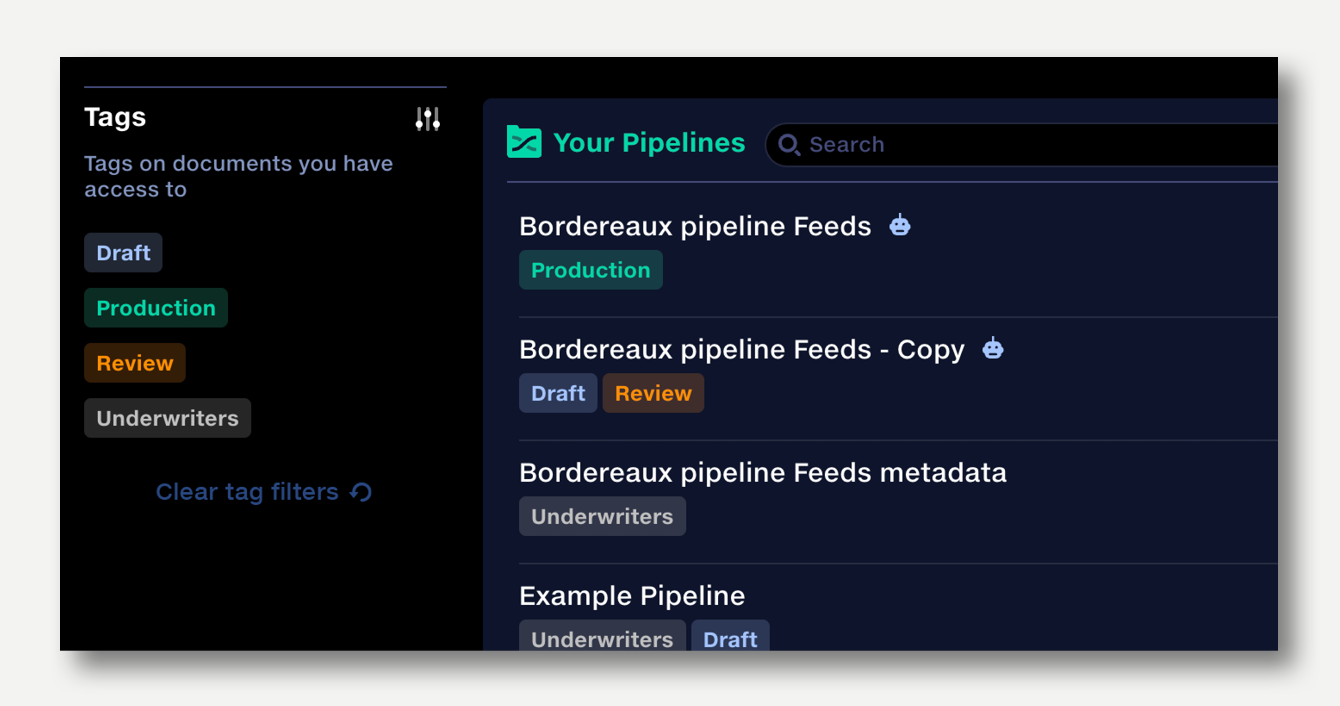
Tags can be applied to any document in Quantemplate to help organise assets.
Tags are created by Org Admins within the repo views for Feeds, Pipelines, Data, and Analyse. They can be applied to documents by document owners. Tags are set at an organisation level and are available to all document types.
Within the repo sidebar, users see all the tags for documents they have access to. Clicking a tag in the sidebar filters the document list by that tag.
Sort, search and filter datasets
Datasets can be sorted by dataset name, updated date, and last updated by user. Click the arrow button to reverse the sort direction.
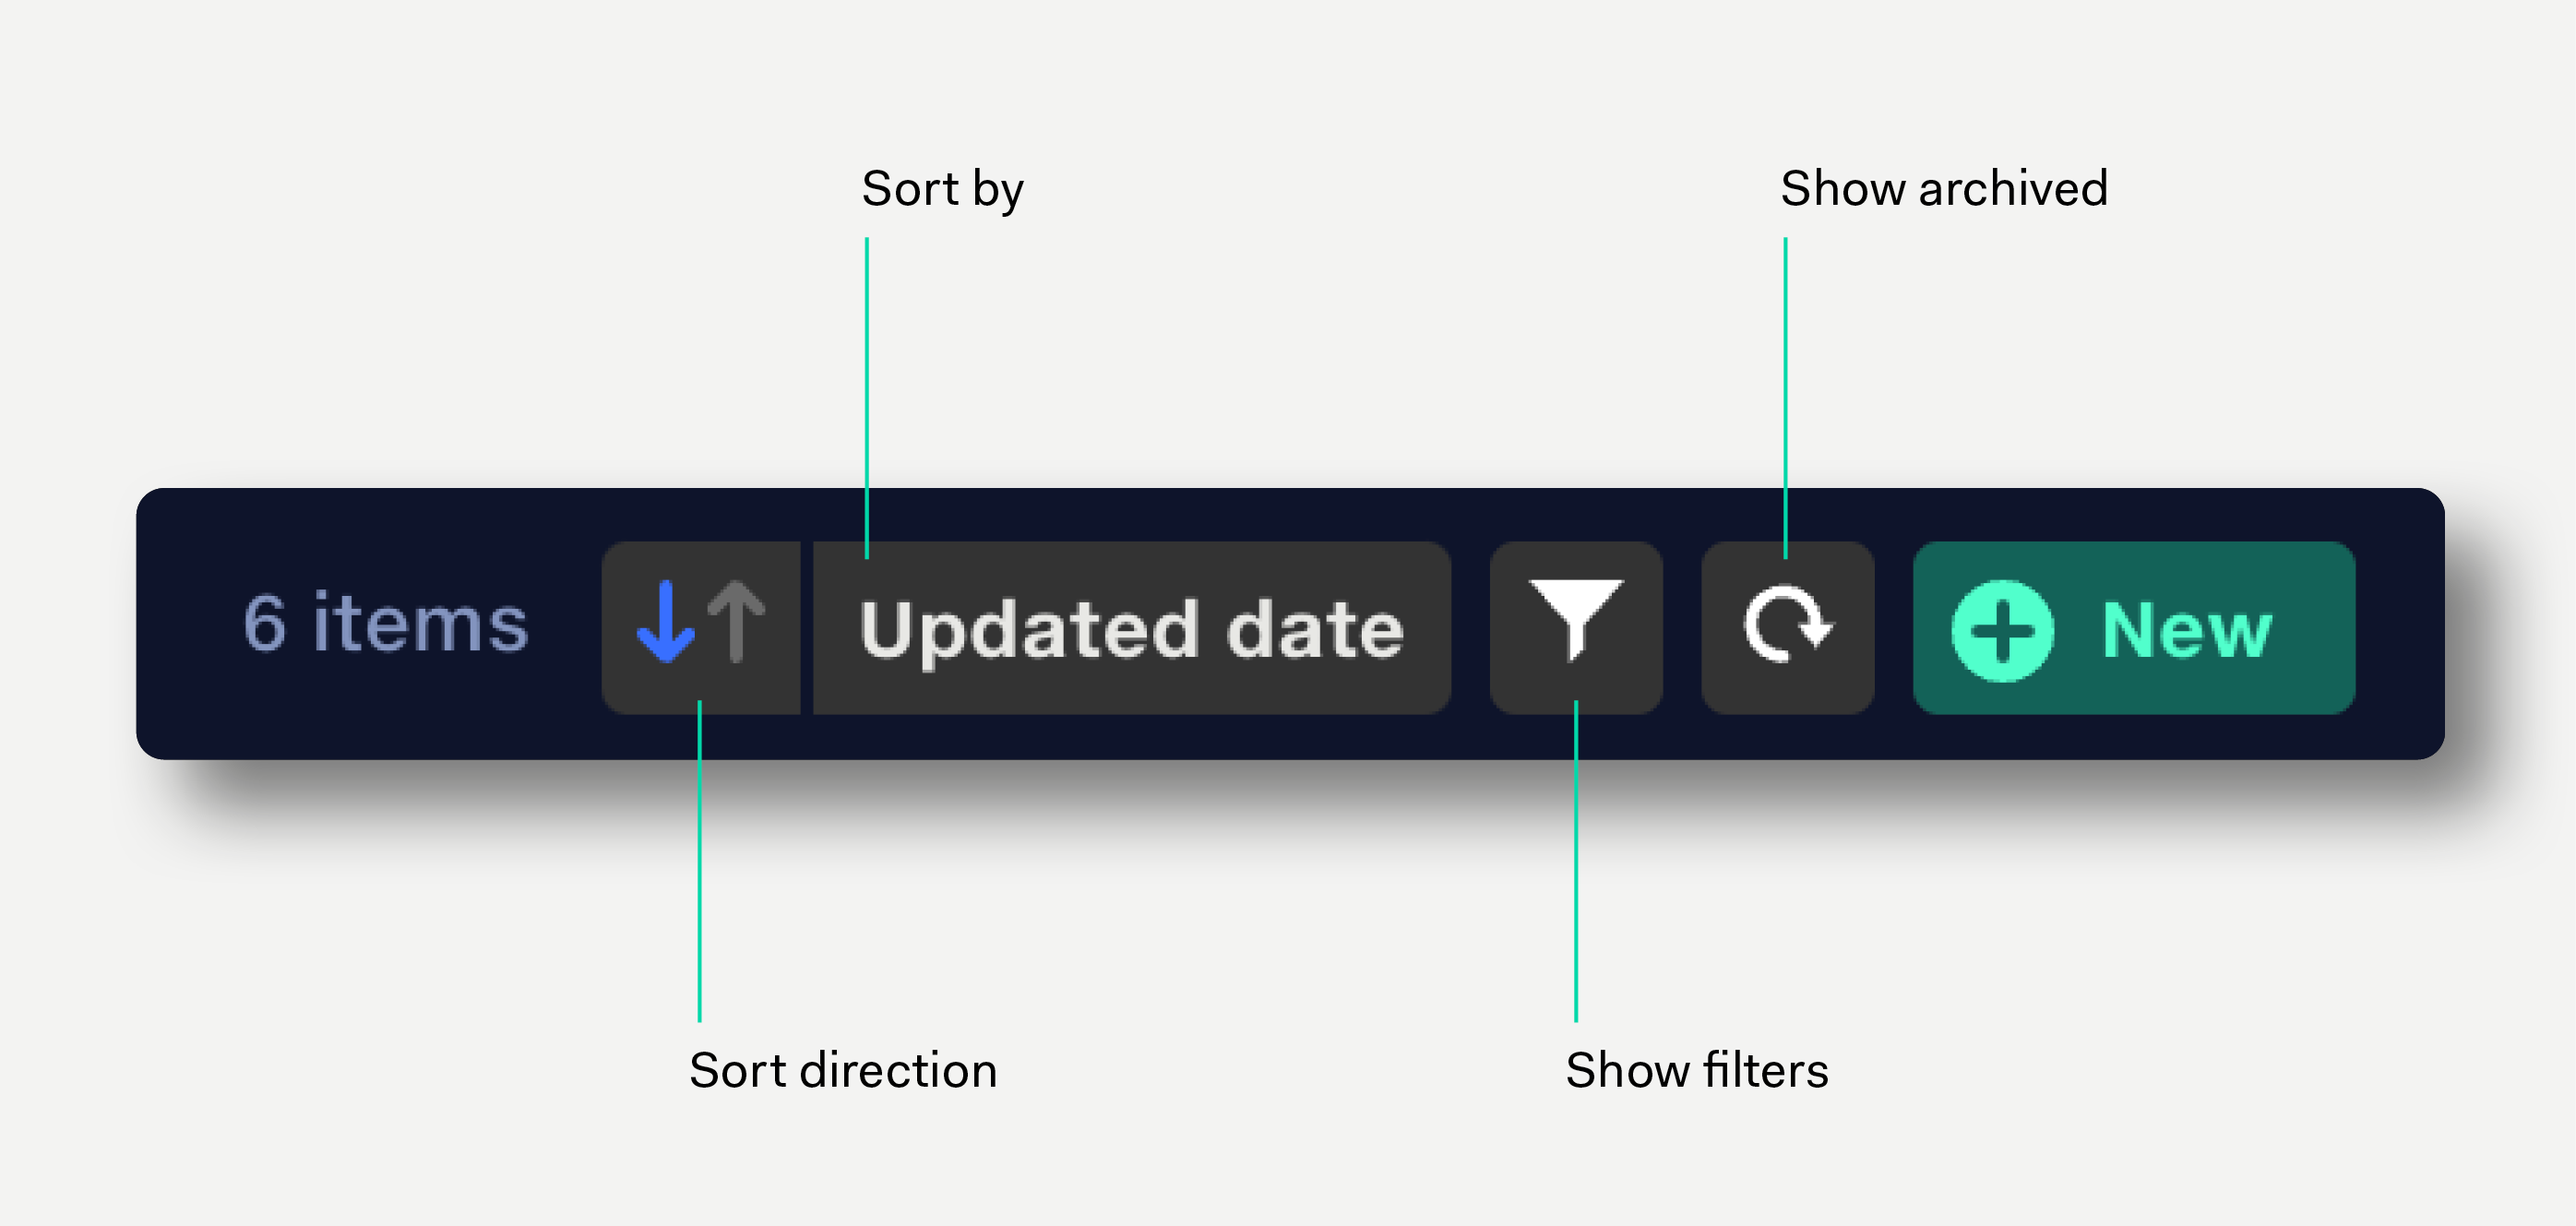
Click in the search field to search datasets by name.
Click the filter icon or press F on the keyboard to filter datasets by date created, date updated, dataset name, owner, and updated by user.
Duplicating datasets
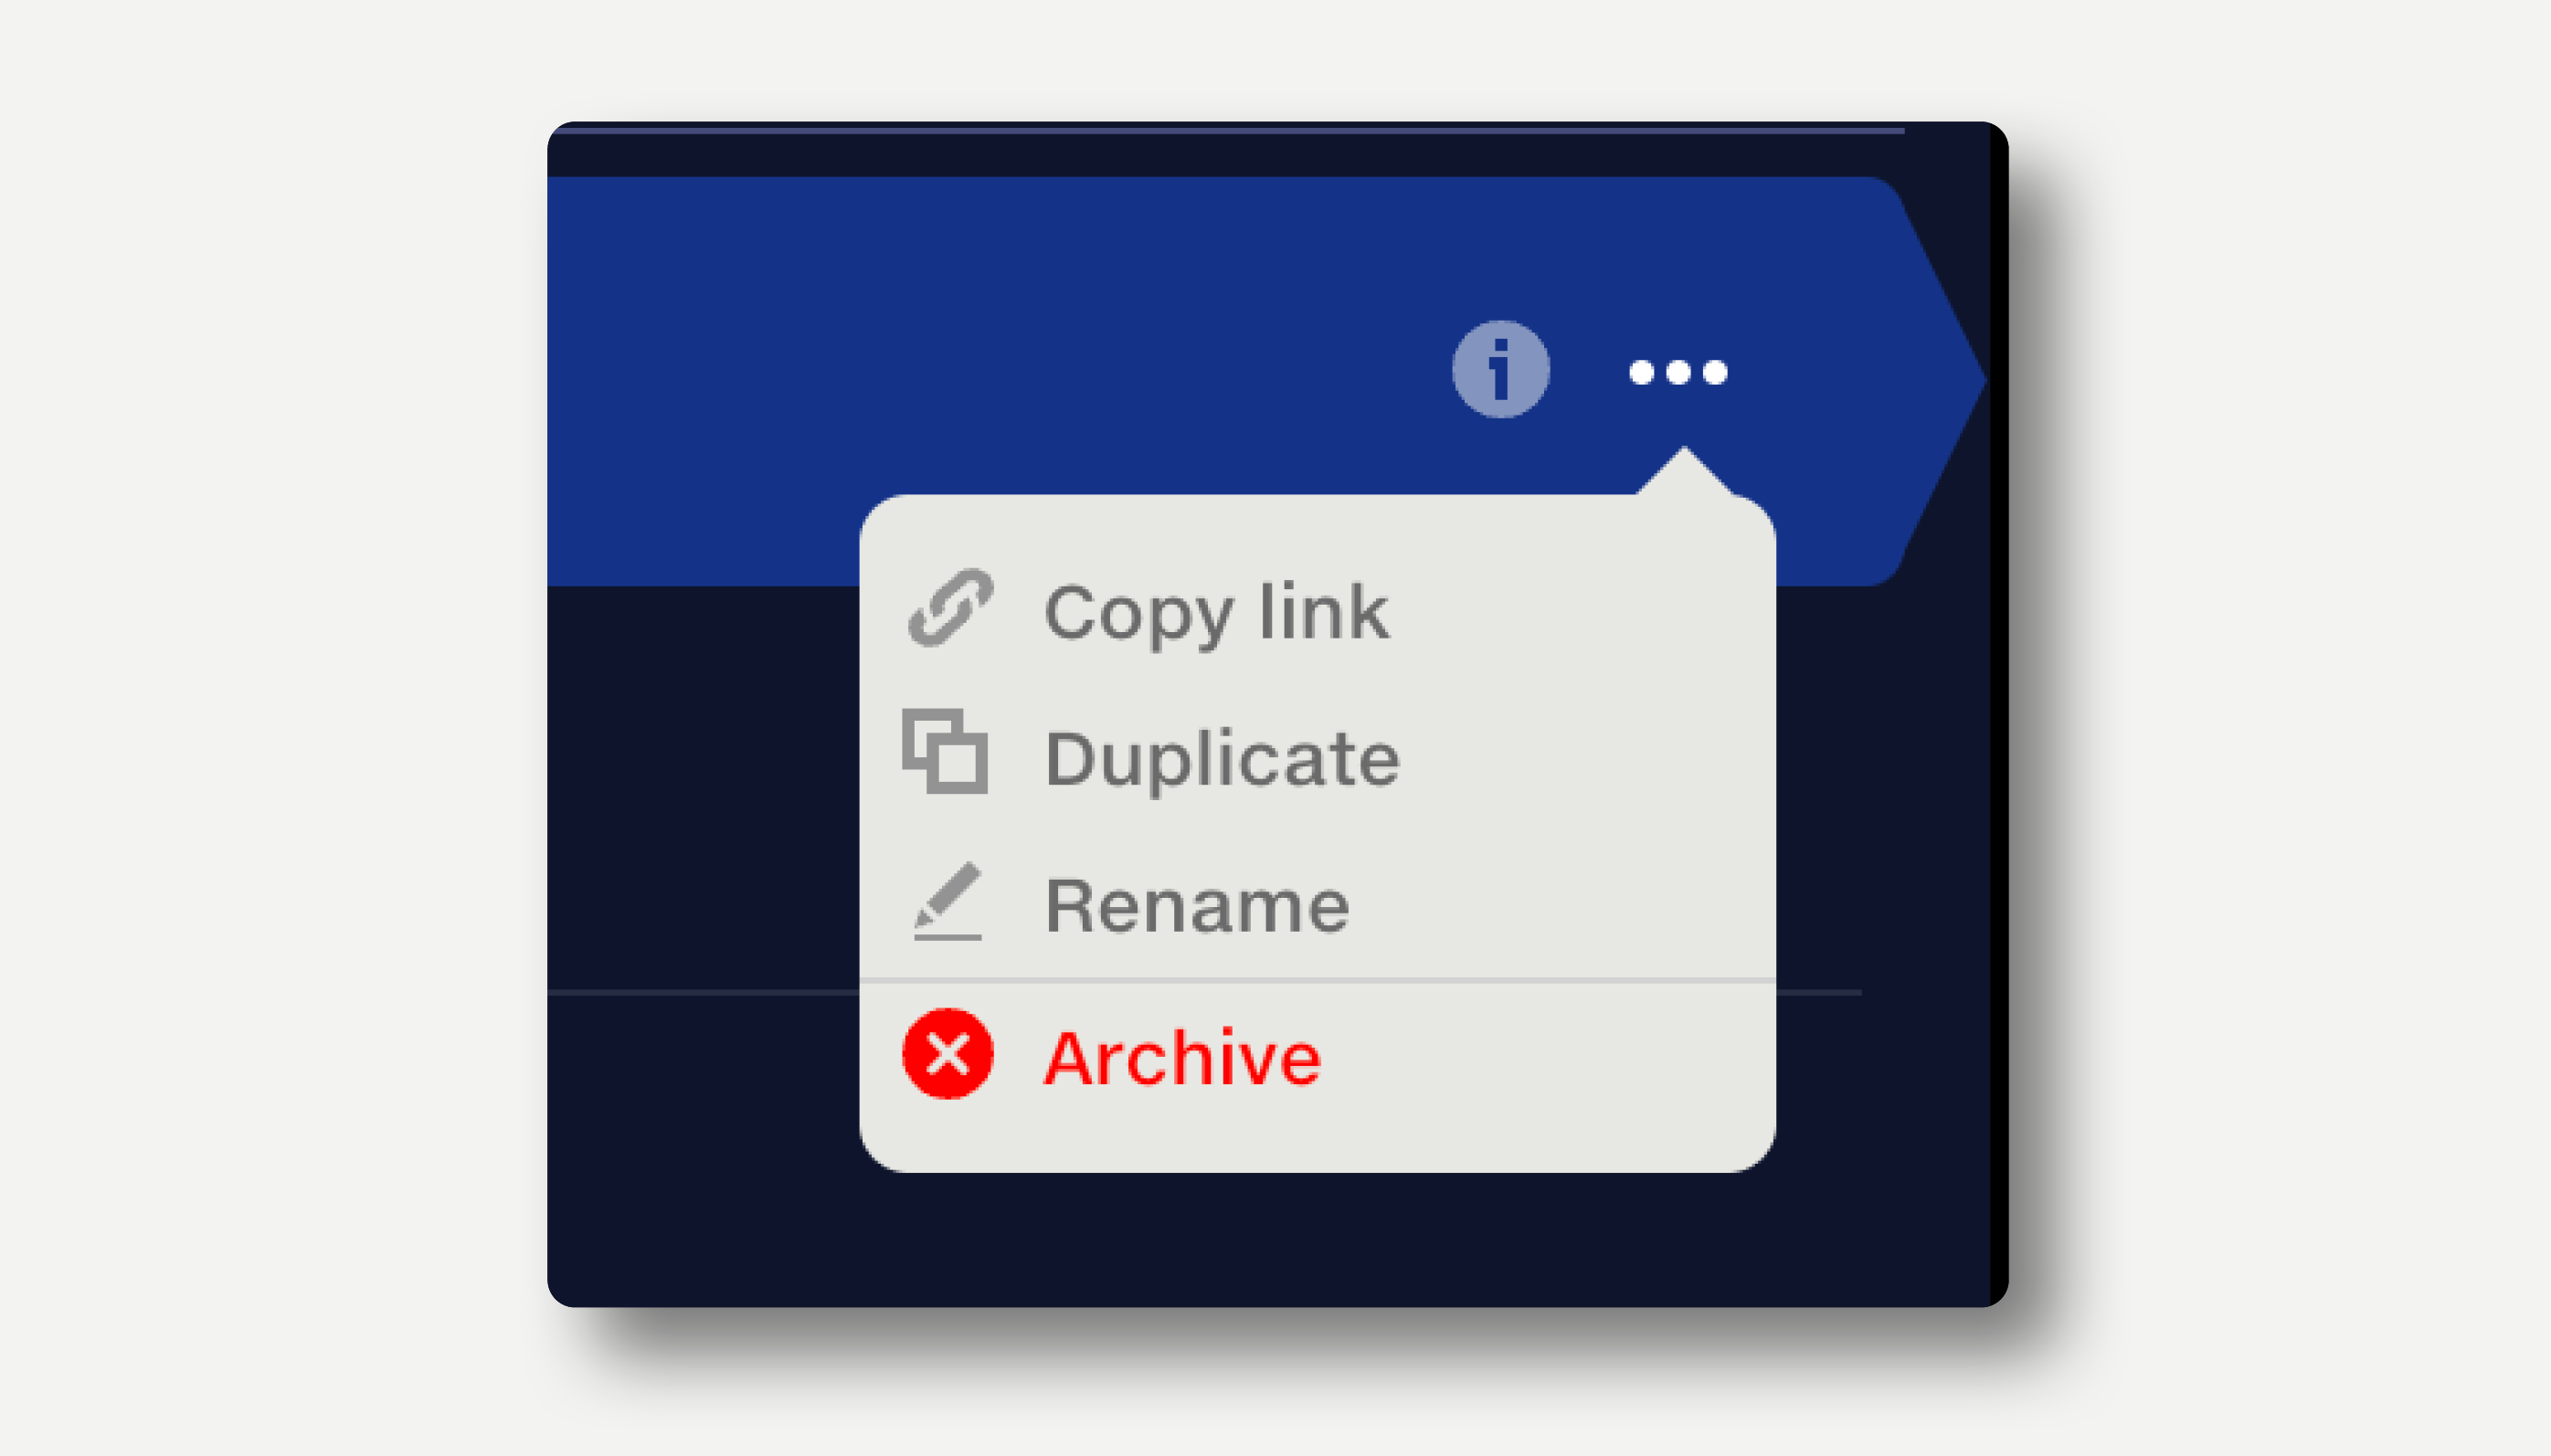
Click the three dots at the end of the row and select ‘Duplicate’ from the popup menu. The dataset is instantly duplicated and the document opened. The suffix ‘copy’ is added to the duplicate dataset’s name.
Renaming datasets
Click the three dots at the end of the row and select ‘Rename’ from the popup menu. Alternatively, edit the dataset name by opening the document and clicking on the name. Name changes propagate throughout the system, and any reports or pipelines using that dataset will display the updated name.
Archiving datasets
Click the three dots at the end of the row and select ‘Archive’ from the popup menu. Archived documents are not deleted, but hidden from the repo and the pipeline input selector.
Archived datasets are ignored by the pipeline and will prevent a pipeline from running if used in a Join stage.
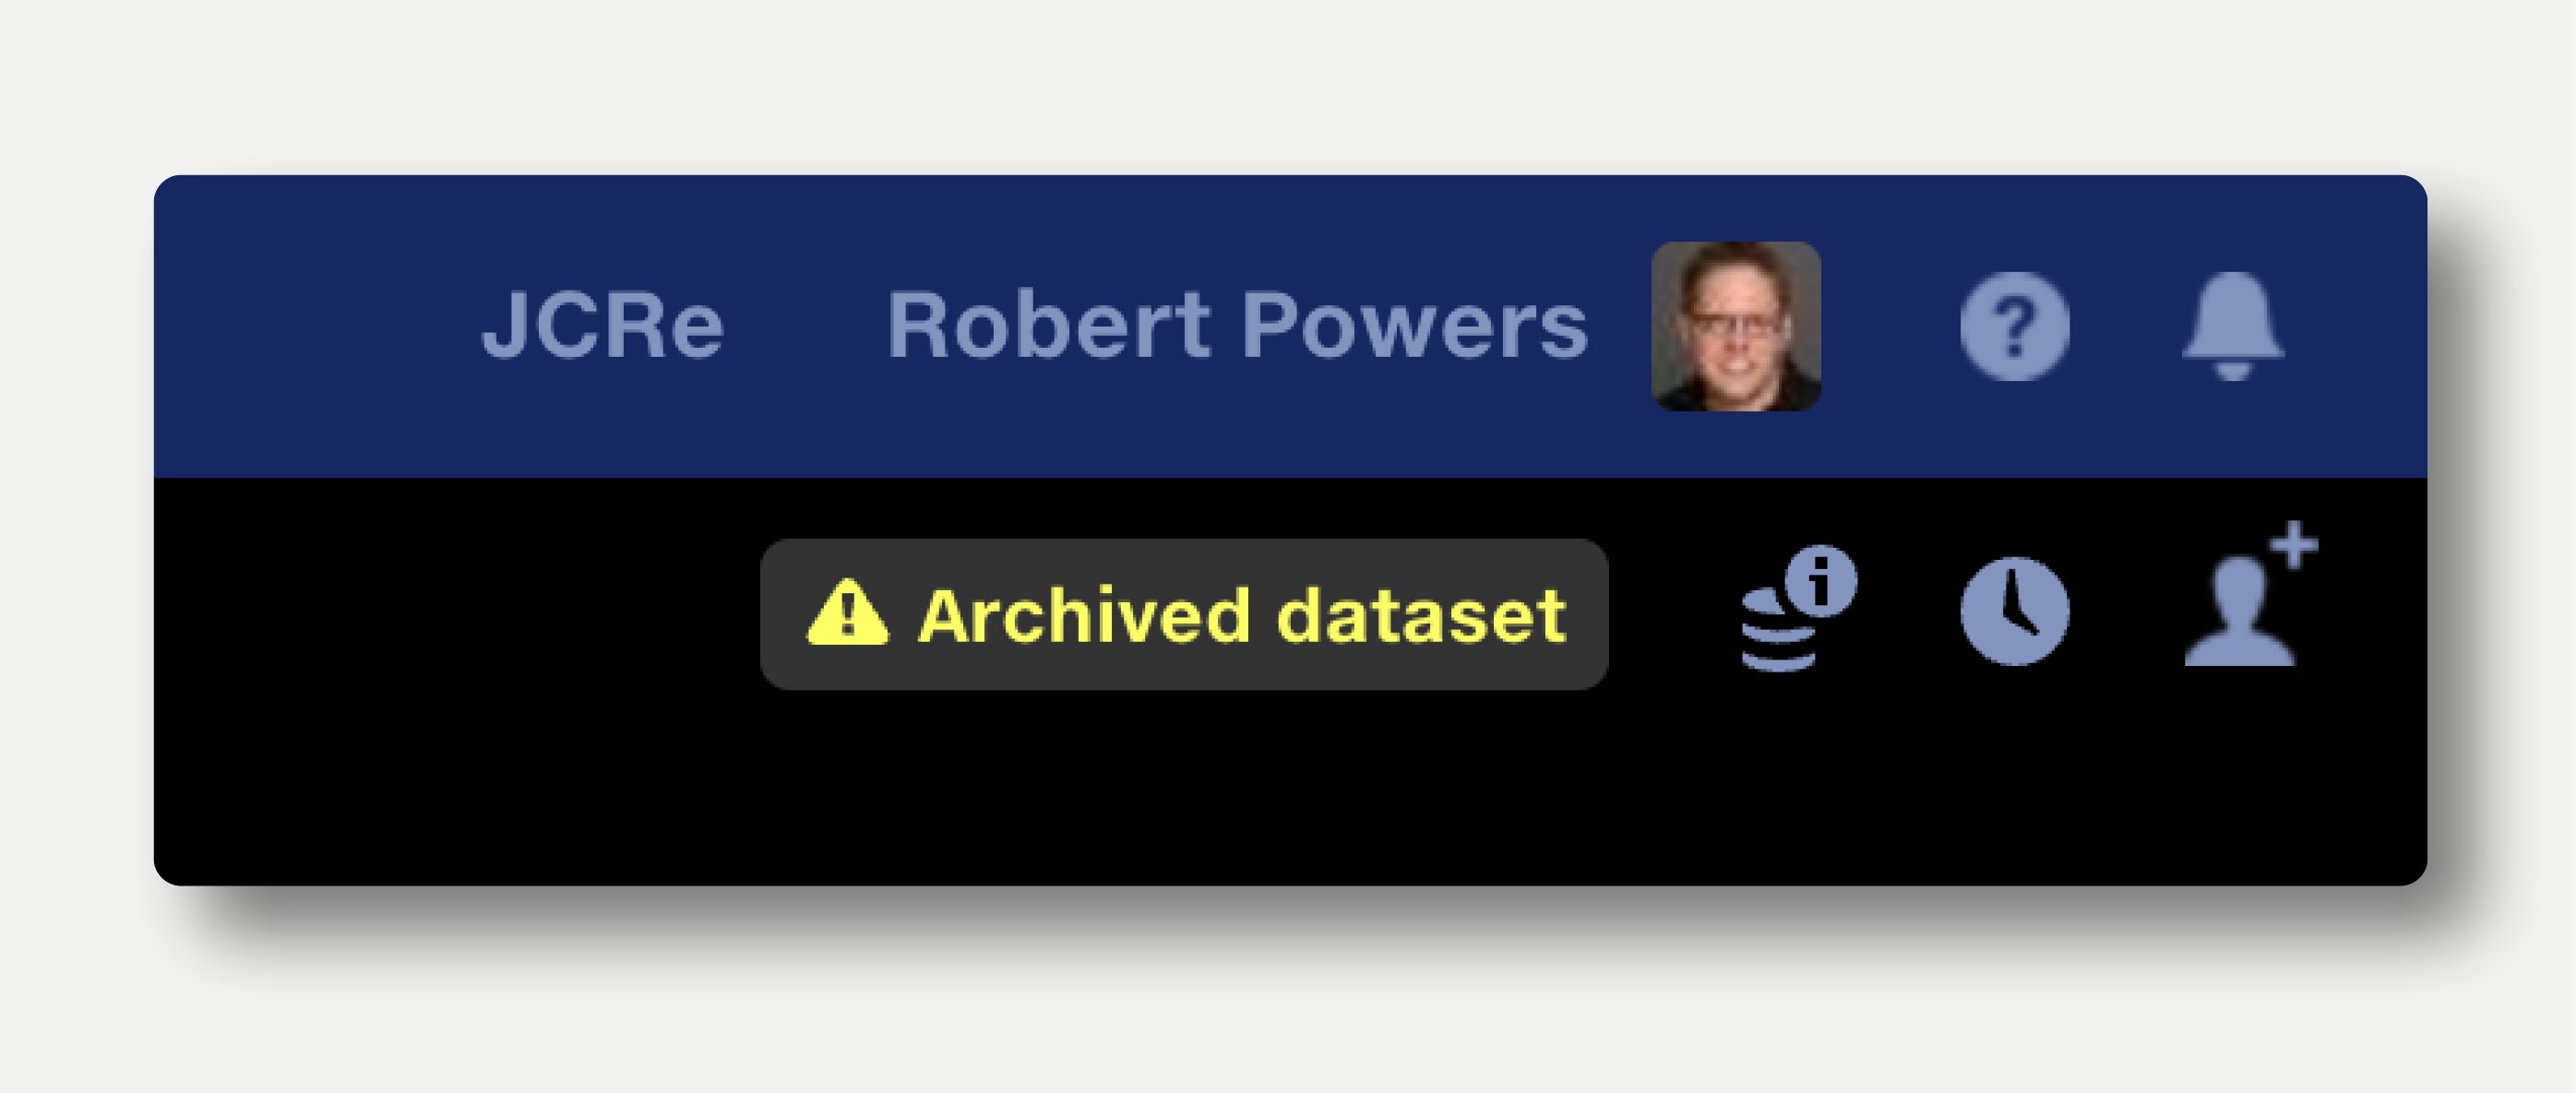
Archived datasets display a warning in the top right of the dataset view.
Note that datasets in Quantemplate cannot be deleted permanently by users. Contact us if you have a specific deletion requirement.
View and restore archived datasets
- To show archived documents, click the ‘Show/hide archived’ button in the top right of the repo, or press A on the keyboard.
- Click a dataset to open it.
- To restore a dataset to the repo, click the three dots at the end of the row and select ‘Restore’.
Creating, uploading and naming datasets

Create a new dataset from within the data view
- Click the + button next to the dataset name. This creates and opens a new empty dataset.
- Name your dataset by clicking on the dataset name.
- Upload your data as XLS, XLSX, CSV, or GZipped CSV files. Drag and drop straight in, or choose a file. Depending on the size of your dataset and the speed of your internet connection, this could take a few minutes.
Create a new dataset from within the repo view
- Open the repo and click the green ‘New’ button at the top right.
- Follow steps 2 and 3 above.
Dataset history
The full change history of a dataset is logged in the Dataset History popup at the top right.
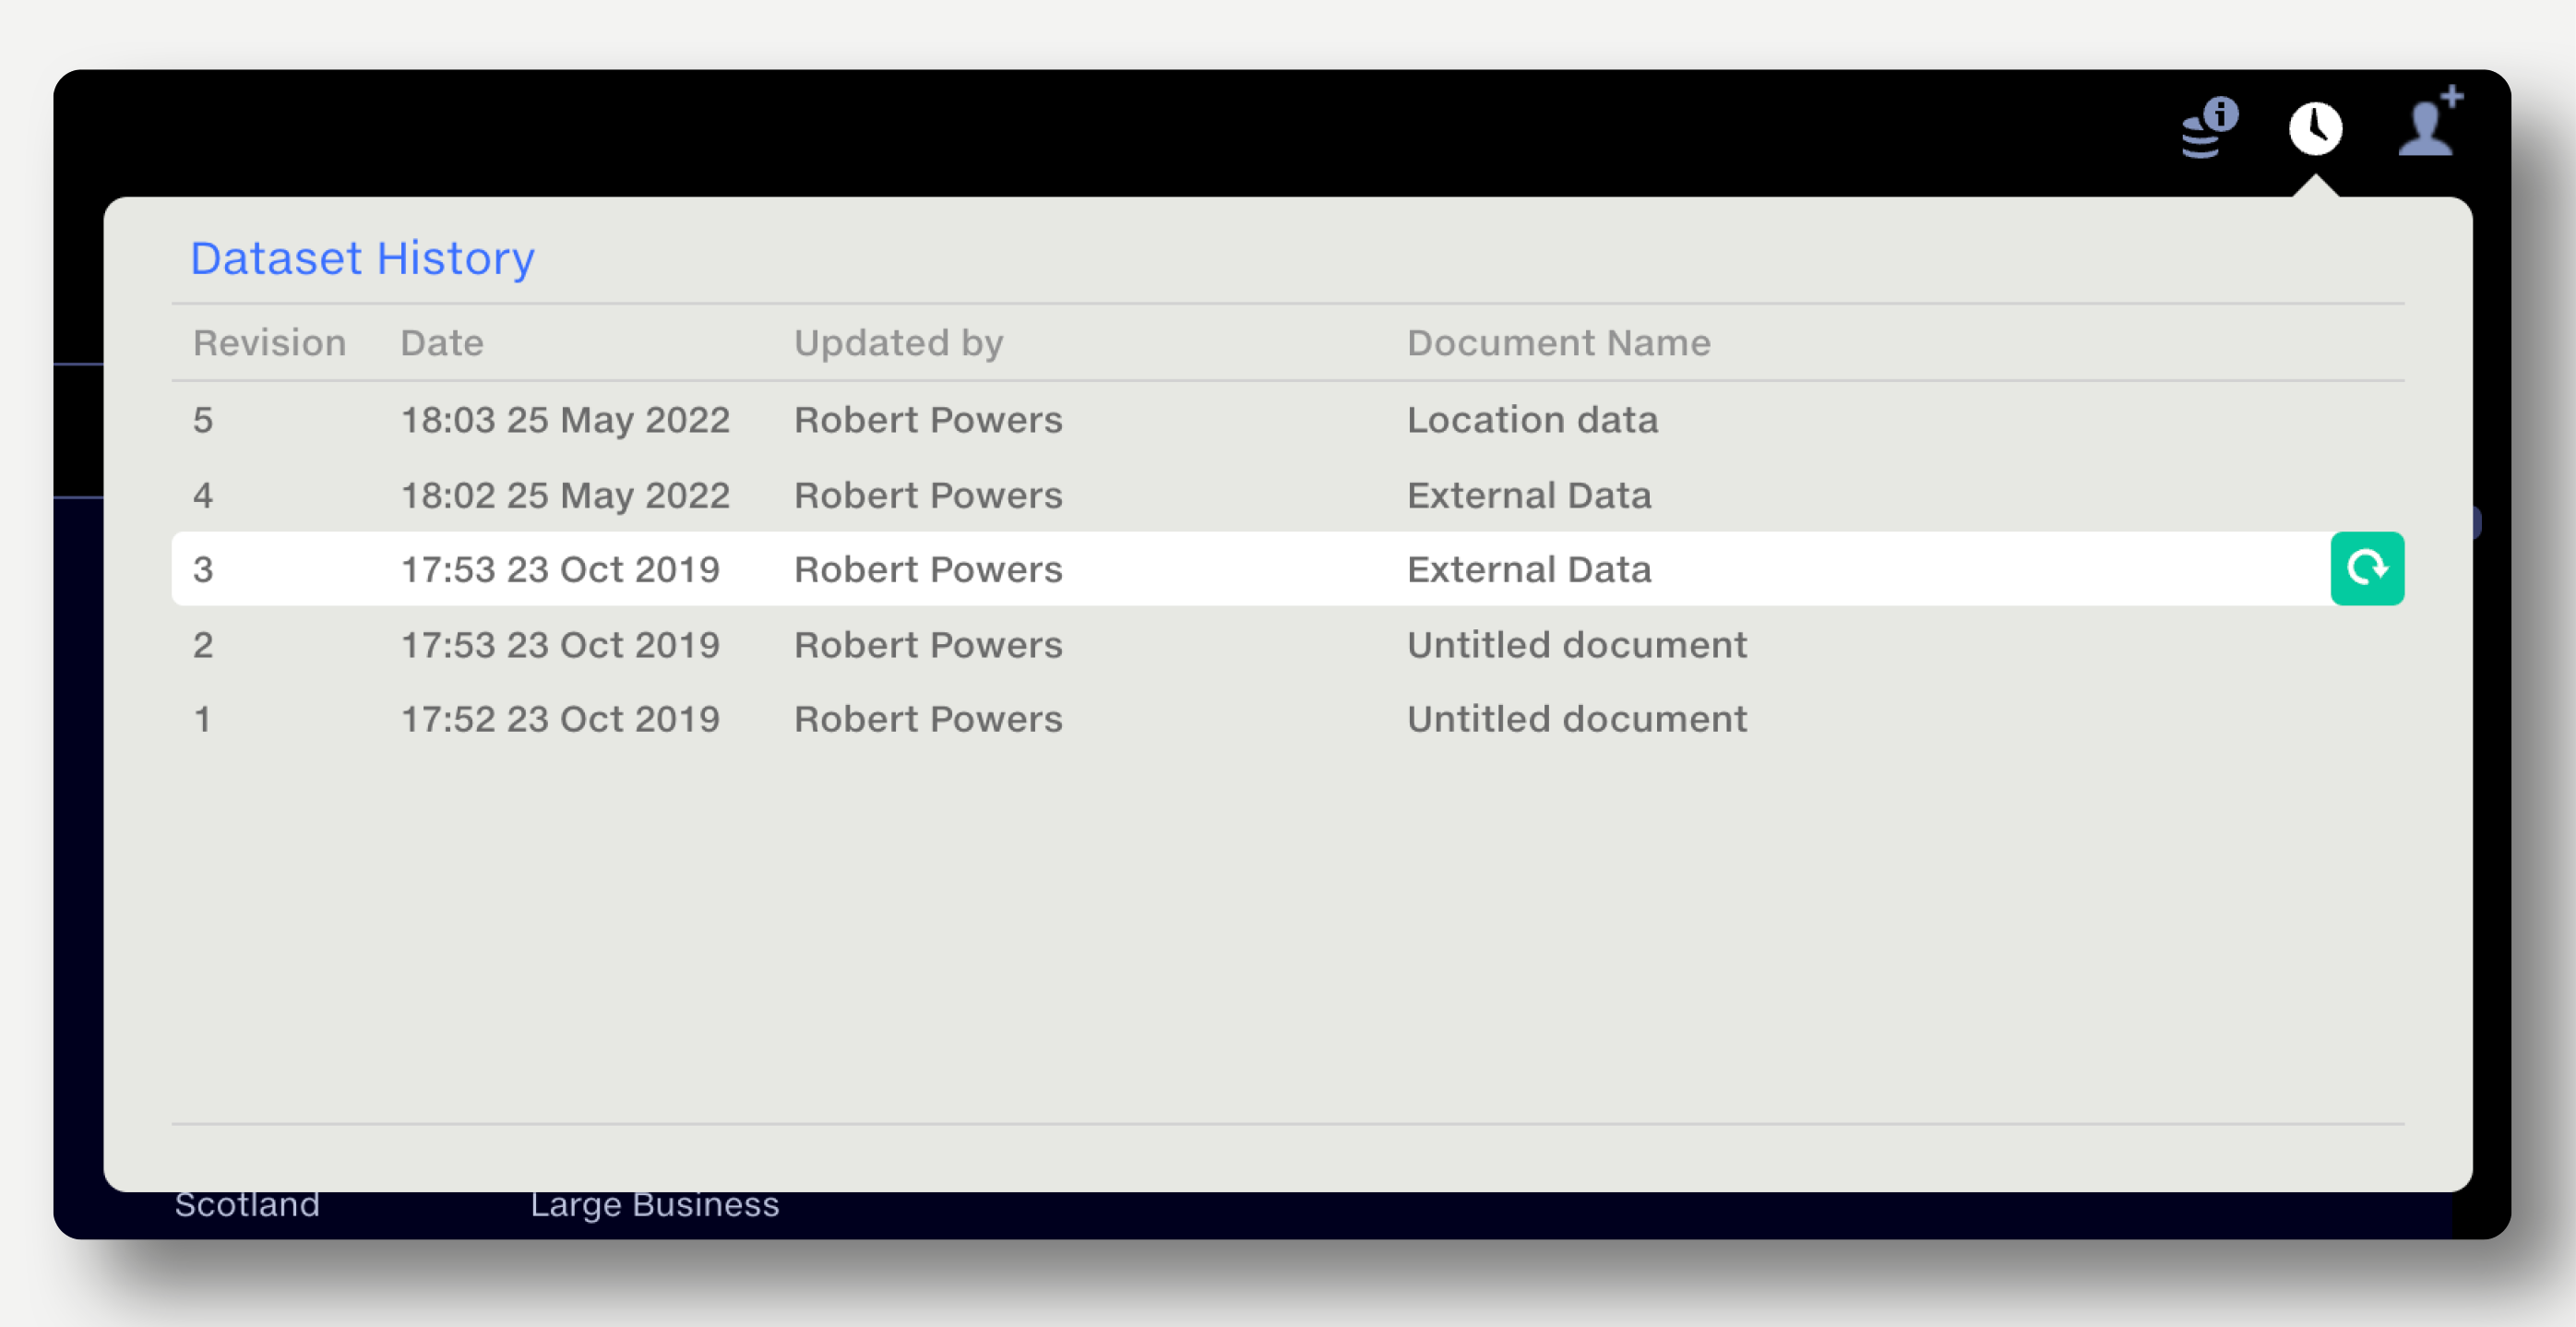
The dataset history shows a dataset’s revision number, date/time of revision, last editor, and the name of the dataset at the time of revision.
Dataset owners and editors can restore a previous version by clicking the green Restore button to the right of the dataset name in the popup. The restored version becomes the latest revision of the dataset.